Database
ArcadeDB in Python: An In-Process Multi-Model Database
arXiv cs.IR0 views
arXiv:2611.07971v1 Announce Type: cross Abstract: Some Python workflows need transactional reads and writes over documents, traversals over a graph, and similarity search over vector embeddings. In practice these are split across separate systems (a document store, a graph engine, and a vector index), and the data is copied between them and kept consistent by application code. ArcadeDB is an open-source multi-model database engine, written in Java, that supports all three access patterns and can be embedded in a host process. We present arcadedb-embedded, a Python package that runs ArcadeDB inside the Python process via JPype, using a Java Runtime Environment bundled in the wheel. One pip install gives a database with documents, a property graph, and vector search, and needs no Java installation. Query results can be returned as Python lists, NumPy arrays, pandas DataFrames, or Arrow tables. We demonstrate a hybrid retrieval workflow that chains vector search, SQL filtering, and graph traversal over one dataset. We benchmark arcadedb-embedded against SQLite, DuckDB, LadybugDB, and Chroma, and report its costs.
Source:https://arxiv.org/abs/2611.07971PreviousPersistent Retrieval for Conversational Agents: A Study of Retrieval EfficiencyNextDecision Models as Retrieval Gates Against Injection and Pollution
Related posts

Prisma Accelerate Retires December 1: A SaaS Migration Guide
0dev.to
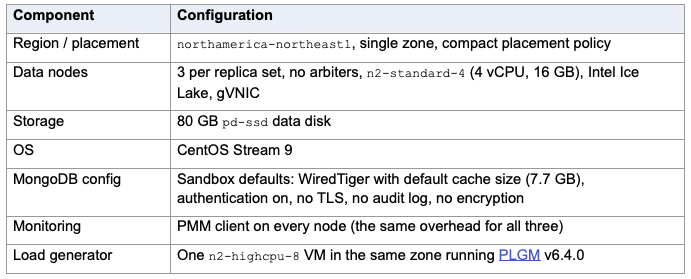
MongoDB 9.0 vs. 8.0 vs. 8.3: A Quick First Look at Performance
0Percona Blog

OpenBMB's AI Cat Cam Named The Right Cat In All 89 Drinks It Logged
0dev.to News

Renewal Deadline Cron 2026: Cleaning Expired User Sessions and Tokens with Queue Consumers
0dev.to Node

I Built Select: An Open-Source Platform Where AI Agents Earn Their Autonomy
0dev.to OpenSource

Behind ACID: How Databases Actually Implement the 4 Guarantees
0dev.to Database