AI & ML
Beyond Accuracy: Benchmarking Uncertainty Quantification in Retinal Disease Screening
arXiv eess.IV0 views
arXiv:2611.23344v1 Announce Type: new Abstract: Reliable uncertainty quantification (UQ) is essential for evaluating retinal AI systems beyond classification accuracy, yet it remains unclear whether existing UQ strategies generalize across diseases, model architectures, and reliability criteria. We introduce a large-scale, multi-disease benchmark comprising over $242,000$ fundus photographs from $32$ datasets covering diabetic retinopathy, age-related macular degeneration, and glaucoma. We evaluate six representative UQ strategies across three Vision Transformer configurations, assessing discrimination, probabilistic calibration, selective prediction, and conformal prediction-set coverage. Our findings reveal no universally superior model or UQ strategy: methods that improve reliability in one disease or architecture may underperform in another, while improvements in discrimination, calibration, and selective prediction do not necessarily align. Notably, computationally intensive methods do not consistently outperform simple confidence scores, and domain-specific foundation models and calibration-oriented loss functions do not guarantee greater reliability. In contrast, conformal prediction provides a complementary framework for achieving near-nominal marginal prediction-set coverage across diverse settings, subject to its statistical assumptions. These findings challenge universal UQ recommendations and highlight the need for disease-specific, model-specific, and multidimensional reliability evaluation before clinical deployment. We release standardized dataset splits, trained checkpoints, evaluation code, and an interactive research demonstration to support reproducible benchmarking.
Source:https://arxiv.org/abs/2611.23344PreviousCiGS: Conduction in Gaussian Splats for Interior Temperature Field from Thermal ImagesNextSurgCBVR: A Multi-Domain Benchmark for Content-Based Surgical Video-to-Video Retrieval
Related posts
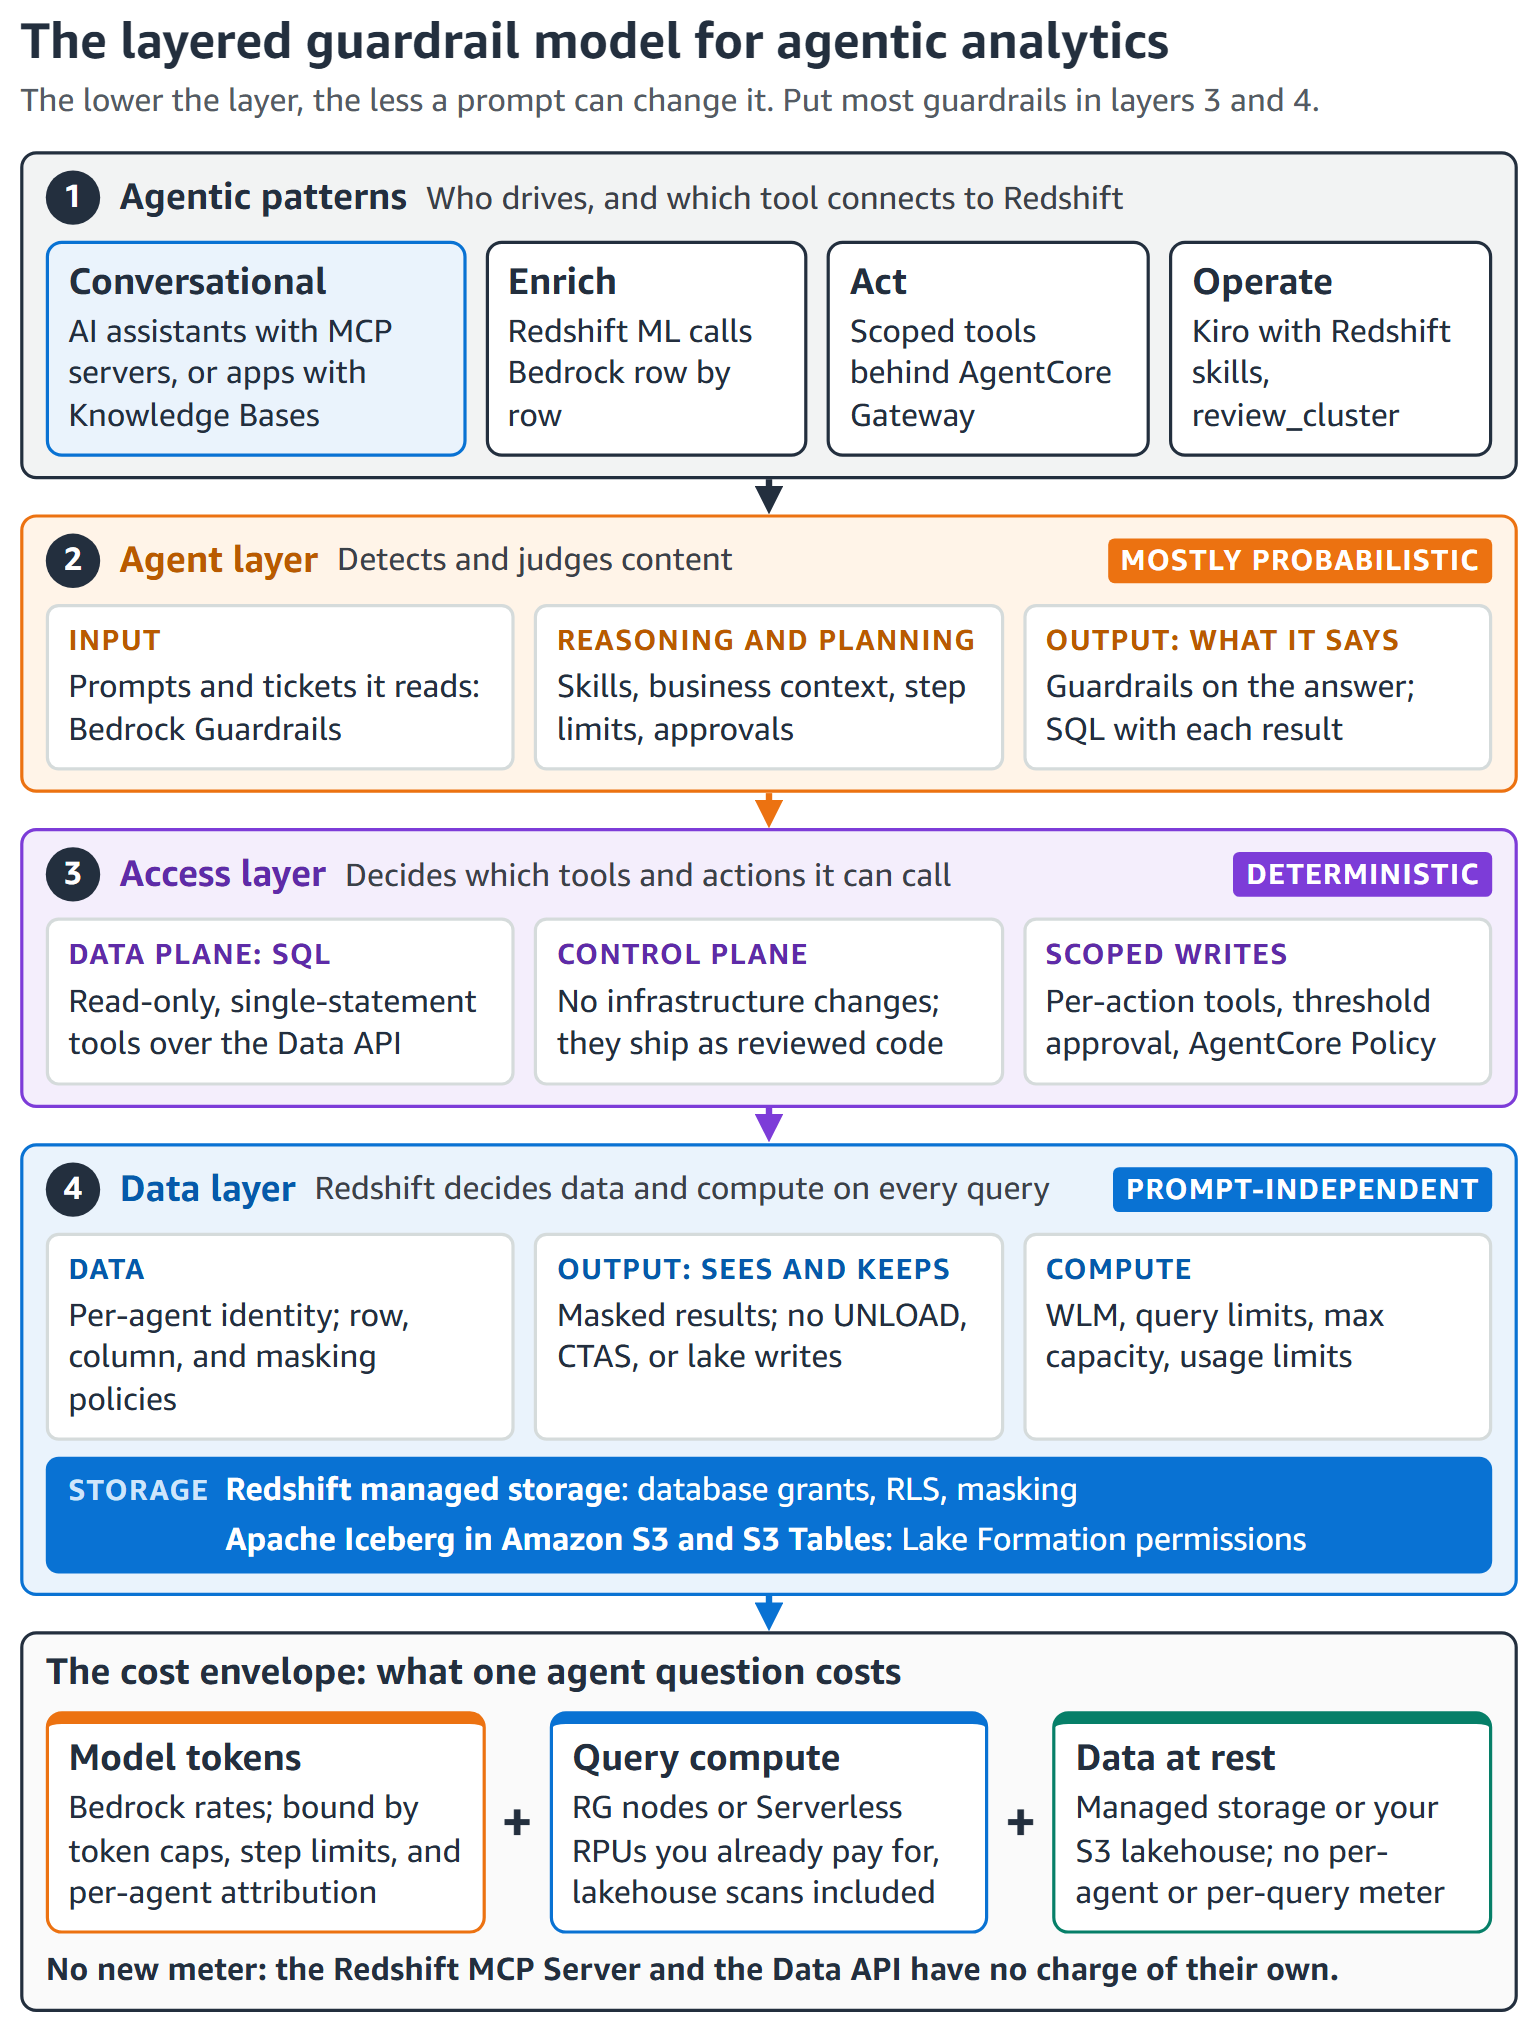
Guardrails and cost control for your agentic workloads with Amazon Redshift
0AWS Big Data Blog
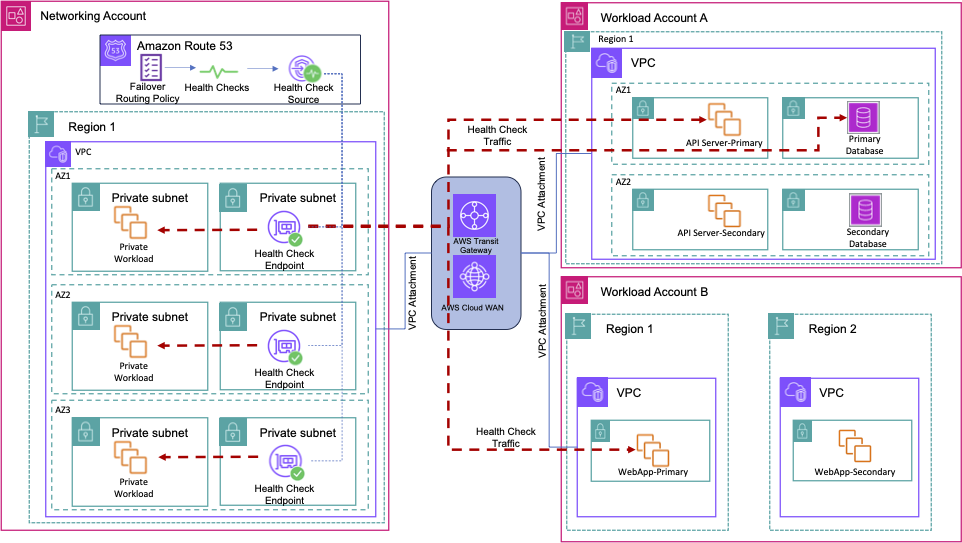
Fast failover with Amazon Route 53 Private Endpoint Health Checks
0AWS Networking Blog
PolyAI Dialog-RSN-1 is now on Amazon SageMaker JumpStart
0AWS Machine Learning Blog
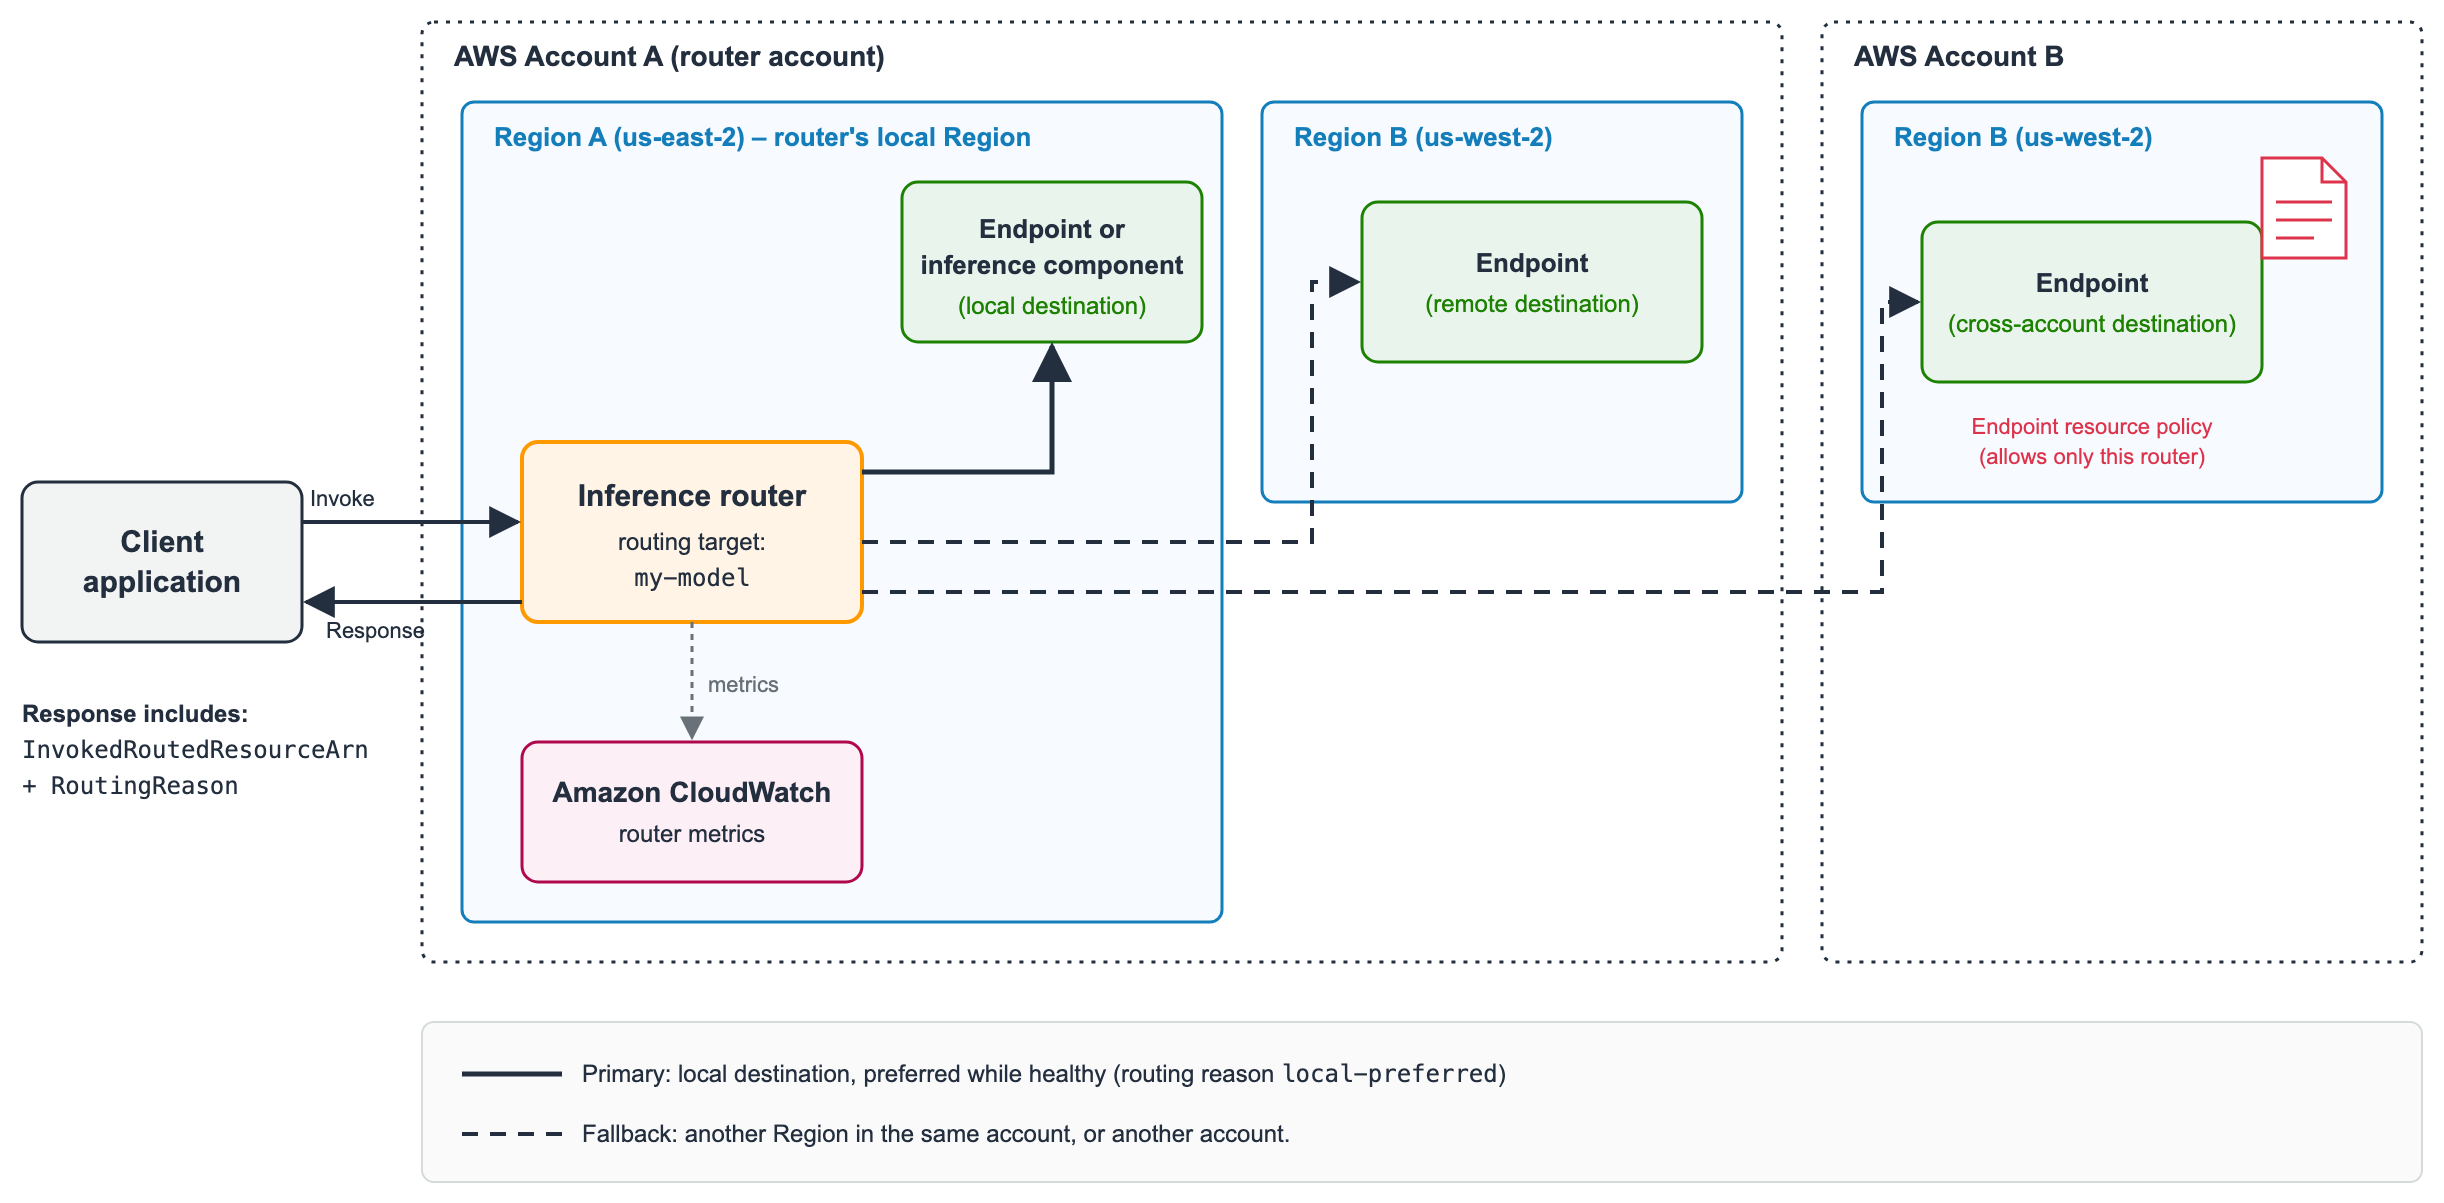
Keep inference running through regional capacity shortfalls with cross-Region inference routing in Amazon SageMaker AI
0AWS Machine Learning Blog
From learning to leaderboard: How Cisco upskilled 1,200 engineers in agentic AI with AWS AI League
0AWS Machine Learning Blog
Optimize AI economics on Amazon Bedrock with Accenture’s sequenced approach
0AWS Machine Learning Blog