Enterprise teams are building multi-agent systems, and when early implementations fall short, the cause is rarely the model. Multi-agent coordination is a distributed systems problem, and many teams taking it on haven’t yet built distributed systems instincts.
The numbers are consistent across sources: ~88% of AI pilots never reach production. Stanford HAI demonstrated that two models can perform worse collaborating than either alone when coordination overhead exceeds the benefit. The pattern is clear: teams are adding complexity faster than they build understanding. Ten steps that are each 95 percent reliable deliver only 59.9 percent end-to-end reliability, and 20 steps deliver 35.8 percent. This illustrative model assumes a strictly sequential chain with no retries, but the direction holds: each dependent handoff multiplies risk.
In this post, you learn how to decide whether a use case needs multiple agents, choose a coordination pattern, and spot costly anti-patterns early. You also see how takt time, safety boundaries, edge data, and shift cycles shape the architecture.
Multi-agent coordination patterns
Coordination patterns fall into two tiers, based on who controls the flow. In Tier 1, you define the path.
In Tier 2, the model chooses the path at runtime. That flexibility handles work whose steps you can’t define in advance, at a higher cost in tokens, latency, and debugging. The practical default is to start with Tier 1 and move a task to Tier 2 only when its subtasks emerge during the work.
Tier 1: Patterns (deterministic control flow)
1.1 Sequential Pipeline: Orchestration patterns that implement linear execution where each node’s output feeds into the next node (A -> B -> C) supporting ordered processing with predictable execution timing
In the following diagram, input flows to agent A (extract), then agent B (transform), then agent C (validate), and then output. The user defines that order at build time, and nothing is decided at runtime. As a result, the pipeline is straightforward to debug and test, and its cost is predictable. Typical fits include document processing, extract, transform, and load (ETL) chains, and warranty-claim triage.
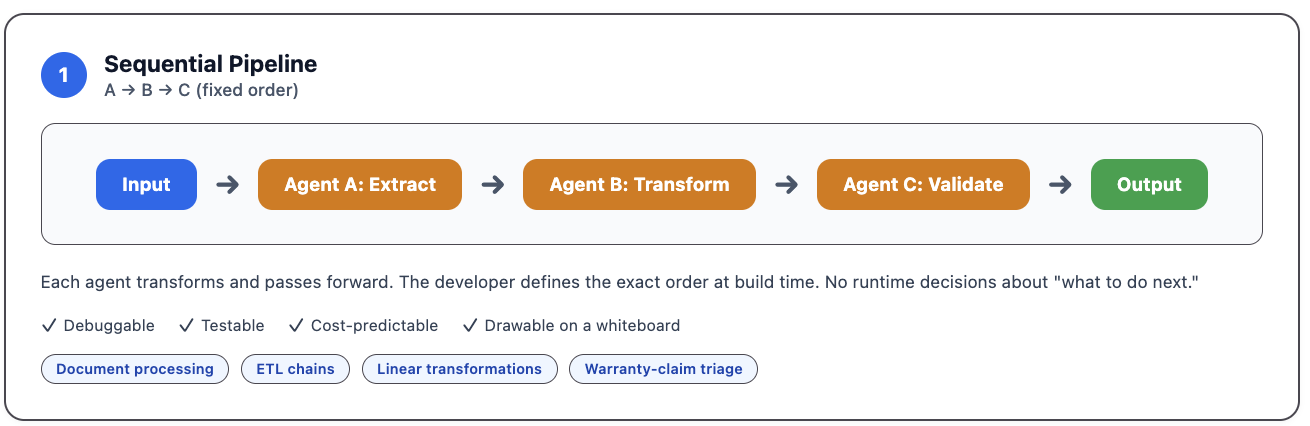
Figure 1: Sequential pipeline where each agent’s output feeds the next, from extract to transform to validate
1.2 Conditional Workflow: Logic-based edges select the next node by condition, so the workflow can branch and send each case down a different path.
In the following diagram, a user request goes to agent A (write code) and then to agent B (test code). A pass/fail check sends passing work to agent D (deploy). Failing work loops back to agent A for a retry, up to a maximum of N times, and then escalates to a human. The orchestration layer enforces that cap, for example through an AWS Step Functions iteration limit, which keeps the loop from becoming the unbounded iteration anti-pattern described later in this post.
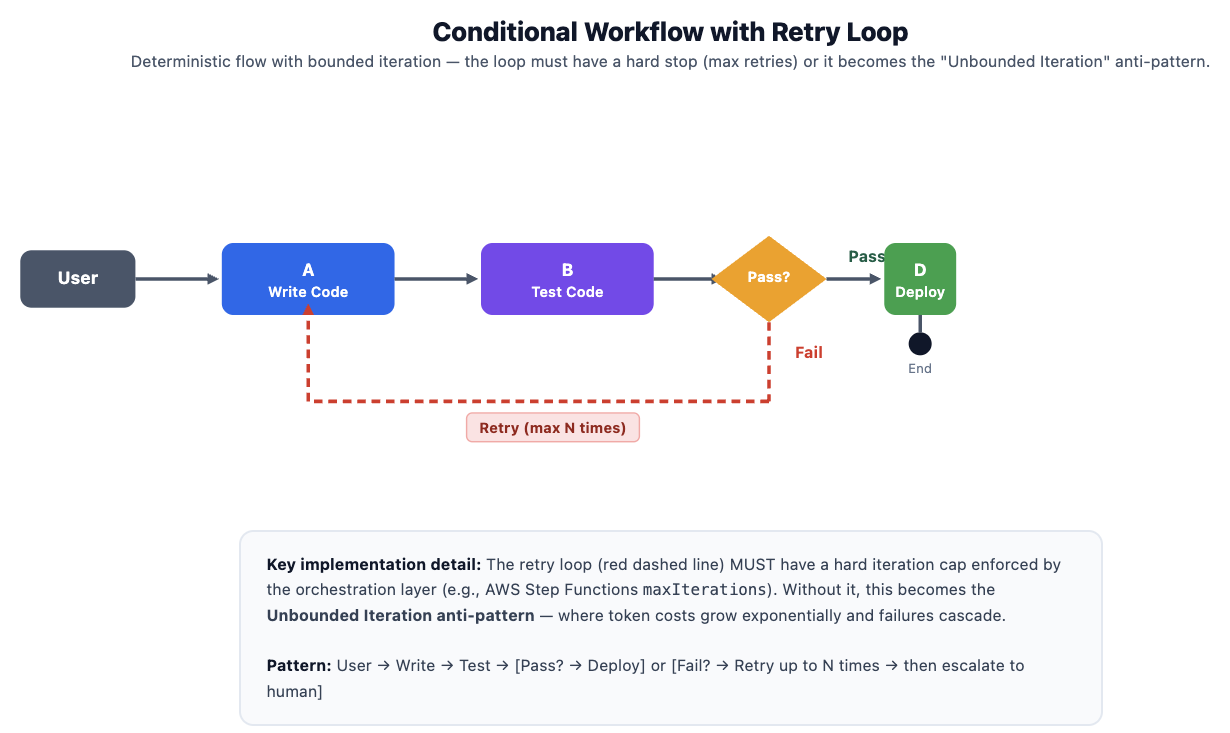
Figure 2: Conditional workflow that retries failures up to N times before escalating to a human
1.3 Conditional Router:
A classification step examines the input and directs it to the appropriate processing path. Only one path is executed per request. Best for intent-driven dispatch, quality-gate decisions, customer inquiry routing, and anomaly triage.
The following diagram shows a plant supervisor’s request being read by a classifier and sent to exactly one specialist. Questions about whether parts meet spec go to the Quality Agent, overdue equipment services go to the Maintenance Agent, and shift changes go to the Scheduling Agent. This decision is made at the entry point.
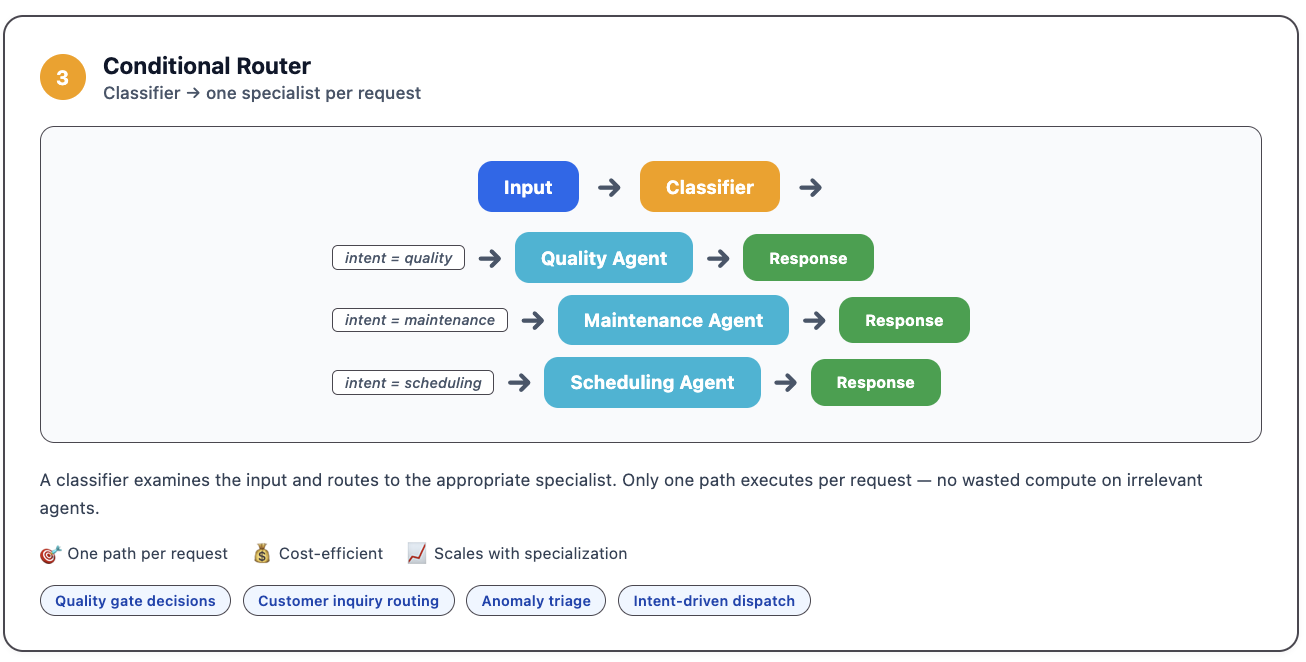
Figure 3: Conditional router that runs one path per request, with bounded retries before human escalation
1.4 Parallel Workflow: A task splits into independent subtasks that run simultaneously across handlers, each on its own data. A fan-in step combines the results when all handlers complete, and a failure in one path retries only that path. Best for multi-source analysis, batch processing, and work that decomposes into independent pieces.
In the following diagram, a research orchestrator decomposes the task and dispatches it to three specialist agents that run concurrently: a financial data agent, a geopolitical agent, and a logistics agent, each analyzing its own source. A combined step waits for all three, then synthesizes the results, resolves conflicts, and ranks the findings. Latency equals the slowest single agent rather than the sum of all three.
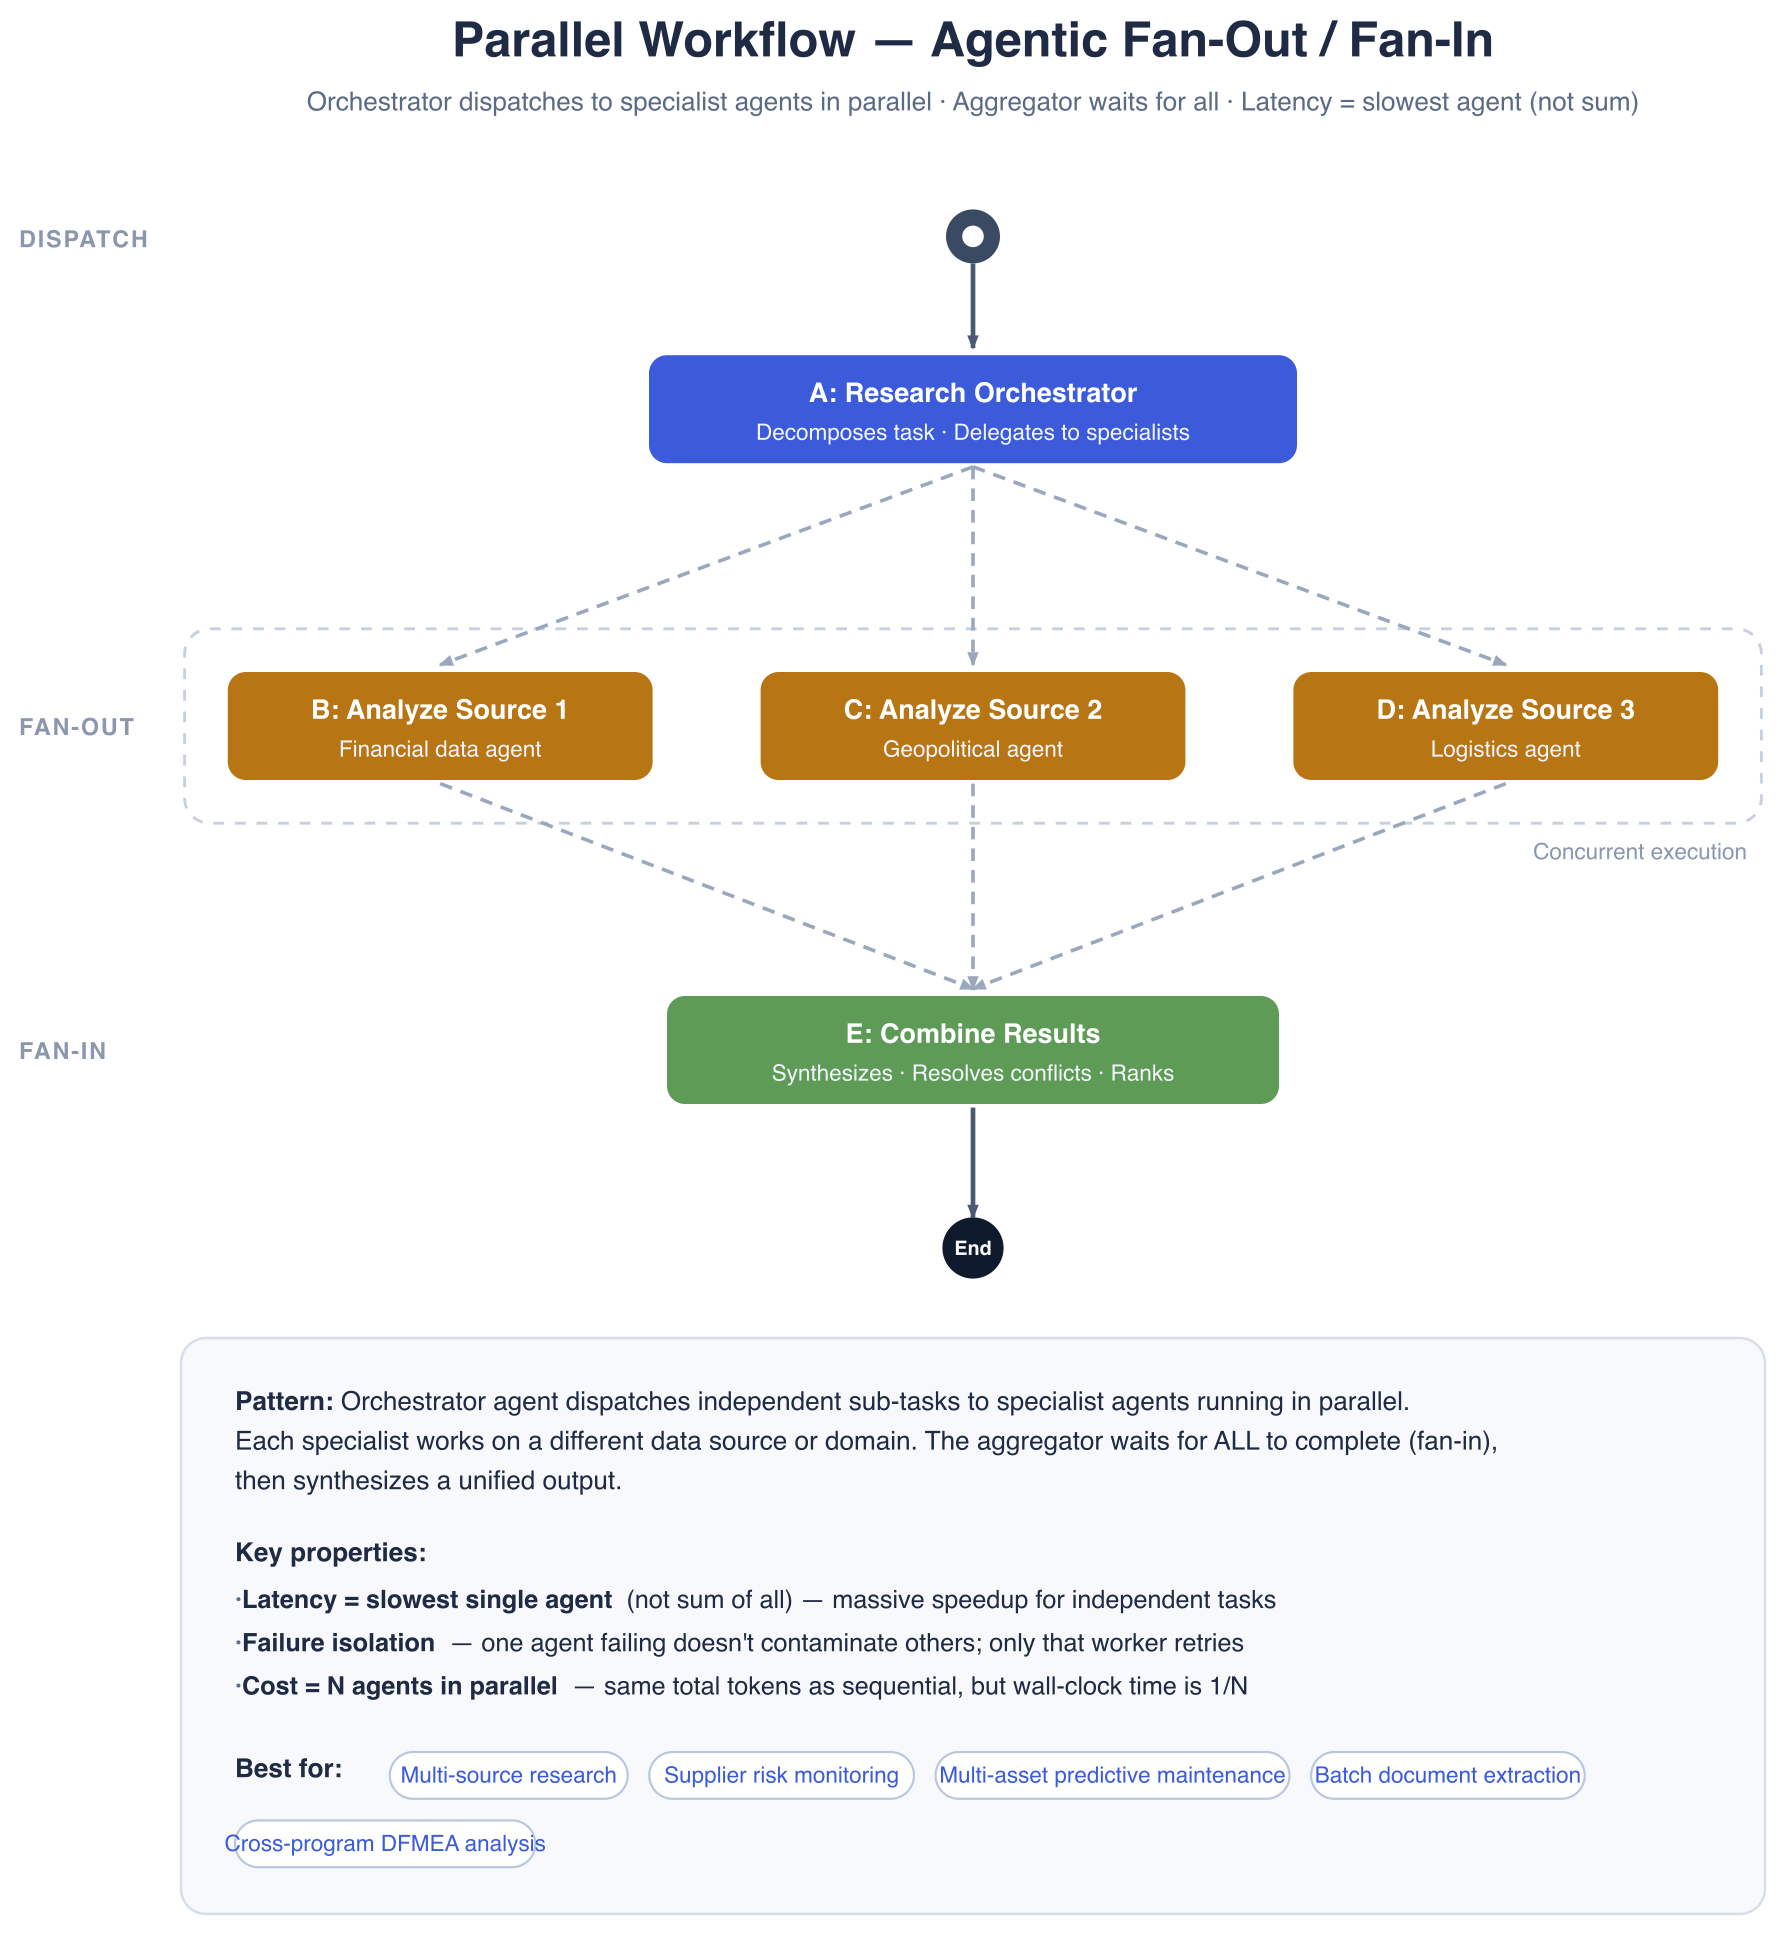
Figure 4: Parallel fan-out to specialist agents followed by a fan-in step that synthesizes and ranks the results
Tier 2: Autonomous patterns (LLM-determined control flow)
In autonomous patterns, control flow is determined at runtime by the AI model itself, not predefined by developers. Agents read task state, reason about what’s needed and coordinate through shared context rather than fixed paths spanning a spectrum from structured orchestration to fully emergent behavior.
2.1 Plan-based orchestration
In plan-based orchestration, a single orchestrator agent acts as a project manager. The orchestrator maintains an explicit task plan with assignments and dependencies, sees all context while each worker receives only its slice, distributes work dynamically against the current plan, and monitors progress centrally. Key design choice is that the workers are stateless and independent. If one fails, it doesn’t contaminate others. The orchestrator retries only the failed worker, not the entire workflow.
The following diagram shows how a planner agent decomposes a task into an explicit plan and dispatches each step to a worker’s agent. Each step goes to a dedicated worker (a research agent, an analysis agent, and a report agent) that sees only its assigned slice.
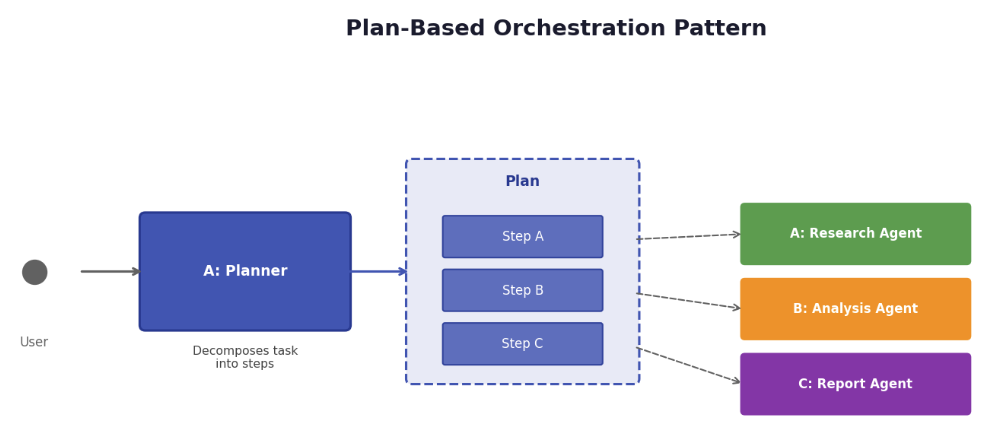
Figure 5: Plan-based orchestration with a planner agent assigning each step to a stateless worker agent
2.2 Handoff pattern
Agents operate with limited, local knowledge and coordinate through peer-to-peer delegation. Each makes local decisions about when and to whom to transfer control, based on the task and the agents it knows. Control passes with state: each transfer carries validated task state, the evidence behind it, and any unresolved questions, so the receiving agent continues rather than reinterpreting a summary. A handoff that moves only through the conversation is not a handoff.
In the following diagram, a customer service agent transfers control, together with its context, to either a technical support agent or a billing agent, and technical support can hand off further to a senior engineer. Each agent knows only the small set of peers it can transfer to.
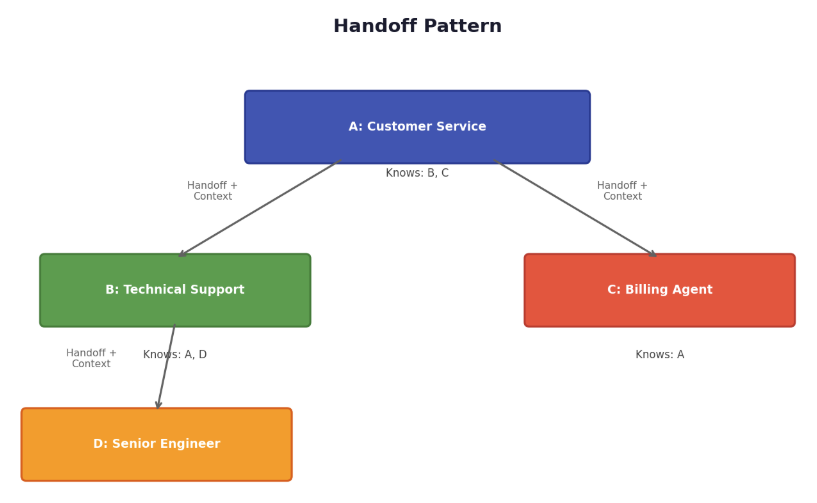
Figure 6: Handoff pattern passing validated state between peer agents through local delegation
2.3 Conversation-driven pattern
In conversation-driven patterns (also known as group chat patterns), all agents participate in a shared conversation where orchestration emerges through turn-taking rather than explicit plans or structured handoffs. This mirrors human team collaboration where everyone can see the discussion and contribute when appropriate.
In the following diagram, an agent-selection mechanism decides whose turn it is, and agents A, B, and C each add to one shared conversation, where every turn is a message plus a tool call. The selection mechanism sets the turn-taking, and state lives implicitly in the conversation history.
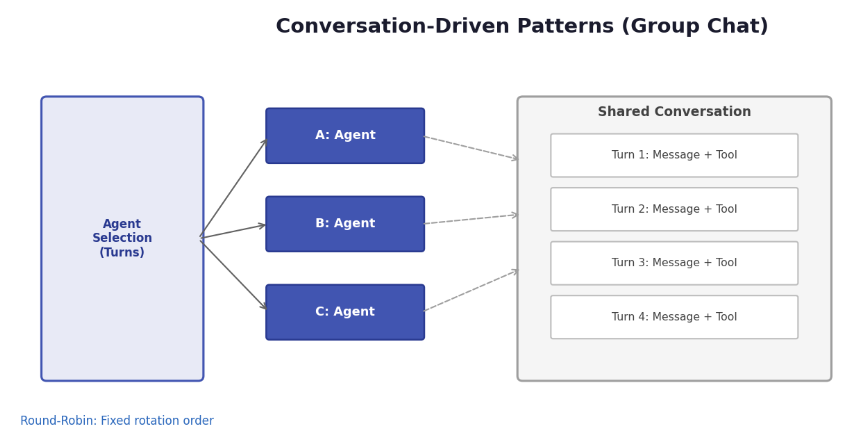
Figure 7: Conversation-driven pattern where turn-taking selects the next agent and state lives in the conversation
Control flow characteristics:
- Visibility: Broadcast all agents observe all messages in the shared conversation.
- Decision making: Next speaker selected based on conversation context, not predetermined plans.
- State management: Implicit in the conversation history.
- Turn-taking: Determined by selection mechanisms (round-robin, AI-driven)
- Round-robin. Agents take turns in a fixed, repeating order until a termination condition is met, which keeps it predictable.
- AI-driven. A model selects the next speaker from the conversation context rather than a fixed order.
2.4 Debate/consensus
Multiple agents independently evaluate the same input, and their conclusions are reconciled by majority, by a judge agent, or by escalation when they disagree. Unlike a conversation-driven pattern, the agents do not see each other’s reasoning before committing to a position, which is what makes disagreement informative rather than socially convergent.
Use it sparingly. Debate is the most expensive pattern here, and on perceptual tasks it buys latency rather than accuracy (see the quality-inspection case in anti-pattern 3 that follows). Reserve it for high-stakes, low-volume decisions where being wrong costs more than deliberating.
Hybrid approaches
In practice, most production systems combine several patterns based on task decomposition:
- Use workflow patterns for predictable, well-understood components.
- Apply autonomous patterns where flexibility and adaptation are essential.
- Implement task management patterns (termination, delegation) consistently across all orchestration types.
- Design hierarchical compositions where complex agents internally use different patterns at different layers.
The governing principle: pattern-to-task alignment. Match the orchestration approach to each task’s inherent characteristics and your system’s reliability requirements rather than forcing everything through a single pattern.
Anti-patterns that burn budget
Each of the following five anti-patterns looks reasonable at design time, and each surfaces later as an inflated token cost, a missed takt-time window, or a decision that has quietly drifted out of sync with the plant floor.
1. God agent
One agent owns overall equipment effectiveness (OEE) analysis, programmable logic controller (PLC) diagnostics, and maintenance behind a single prompt with 15 or more tools. Tool selection degrades as tools grow, and failures become hard to attribute.
The fix: Bounded agents of five tools or fewer, such as an OEE analyst, a fault diagnostician, and a maintenance drafter.
2. Unbounded iteration
The agent loops on “try again” with no hard stop. A four-agent system can burn a significantly higher number of tokens before a single retry, and no one call trips an alarm. Retries multiply coordination failures rather than fixing them.
The fix: Hard iteration ceiling in code, per-agent token ceiling, budget alarm wired to an automatic stop. Infrastructure enforces limits. The model will not stop itself.
3. Natural-language contracts
Agents hand each other free-text prose with no schema. Interpretation hardens at every hop: “could indicate wear” becomes “confirmed wear” becomes a maintenance order. The drift happens between agents, where tracing is thinnest.
4. Premature multi-agent
Multi-agent where one agent with tool groups would do. Each agent adds a coordination tax that is not linear, and the gains flatten around four. Most “specialists” are one model in different costumes.
The fix: Needs at least two different models, different tool access, concurrent execution, and real interdependency. Fewer than two, and one agent with action groups does it.
The test: can one agent handle the phases by switching tools? Then it is not a multi-agent problem.
5. Unguarded customer contact
The agent triggers real-world actions (email, service visits, machine parameters) with no approval step. Hallucinations cross into the physical world, irreversible actions compound, and liability escalates from a refund to product liability.
The fix: Defense in depth: recommendation → Amazon Bedrock Guardrails → schema validation → business rules → human approval → execution.
Every point where agent output reaches a customer, or a safety system is a trust boundary.
Choosing an architecture
With the patterns and anti-patterns in view, the architecture choice comes down to a short sequence of questions.
- Does the task require action beyond text generation? Treat a direct model call as the baseline and add orchestration only for a measured reason. Summarizing documents or generating code from a specification rarely supplies one.
- Is the solution path known in advance? If you can write down what happens in what order, you don’t have a “how many agents” decision at all. Your real choice is simpler: a single agent that calls tools, or a Tier 1 workflow.
- Does the work require genuinely distinct expertise? Separate domains with established handoffs justify specialized agents. A single domain belongs to one agent, no matter how many tools it needs.
- Does the solution emerge only through exploration? When the action sequence is known and can run as an act-and-validate loop, it belongs to a single agent, even one that plans its steps dynamically. Tier 2 earns its added cost, latency, and debugging burden only when the subtasks themselves are discovered in the course of the work.
The following decision tree turns these four questions into a path you can follow from top to bottom.
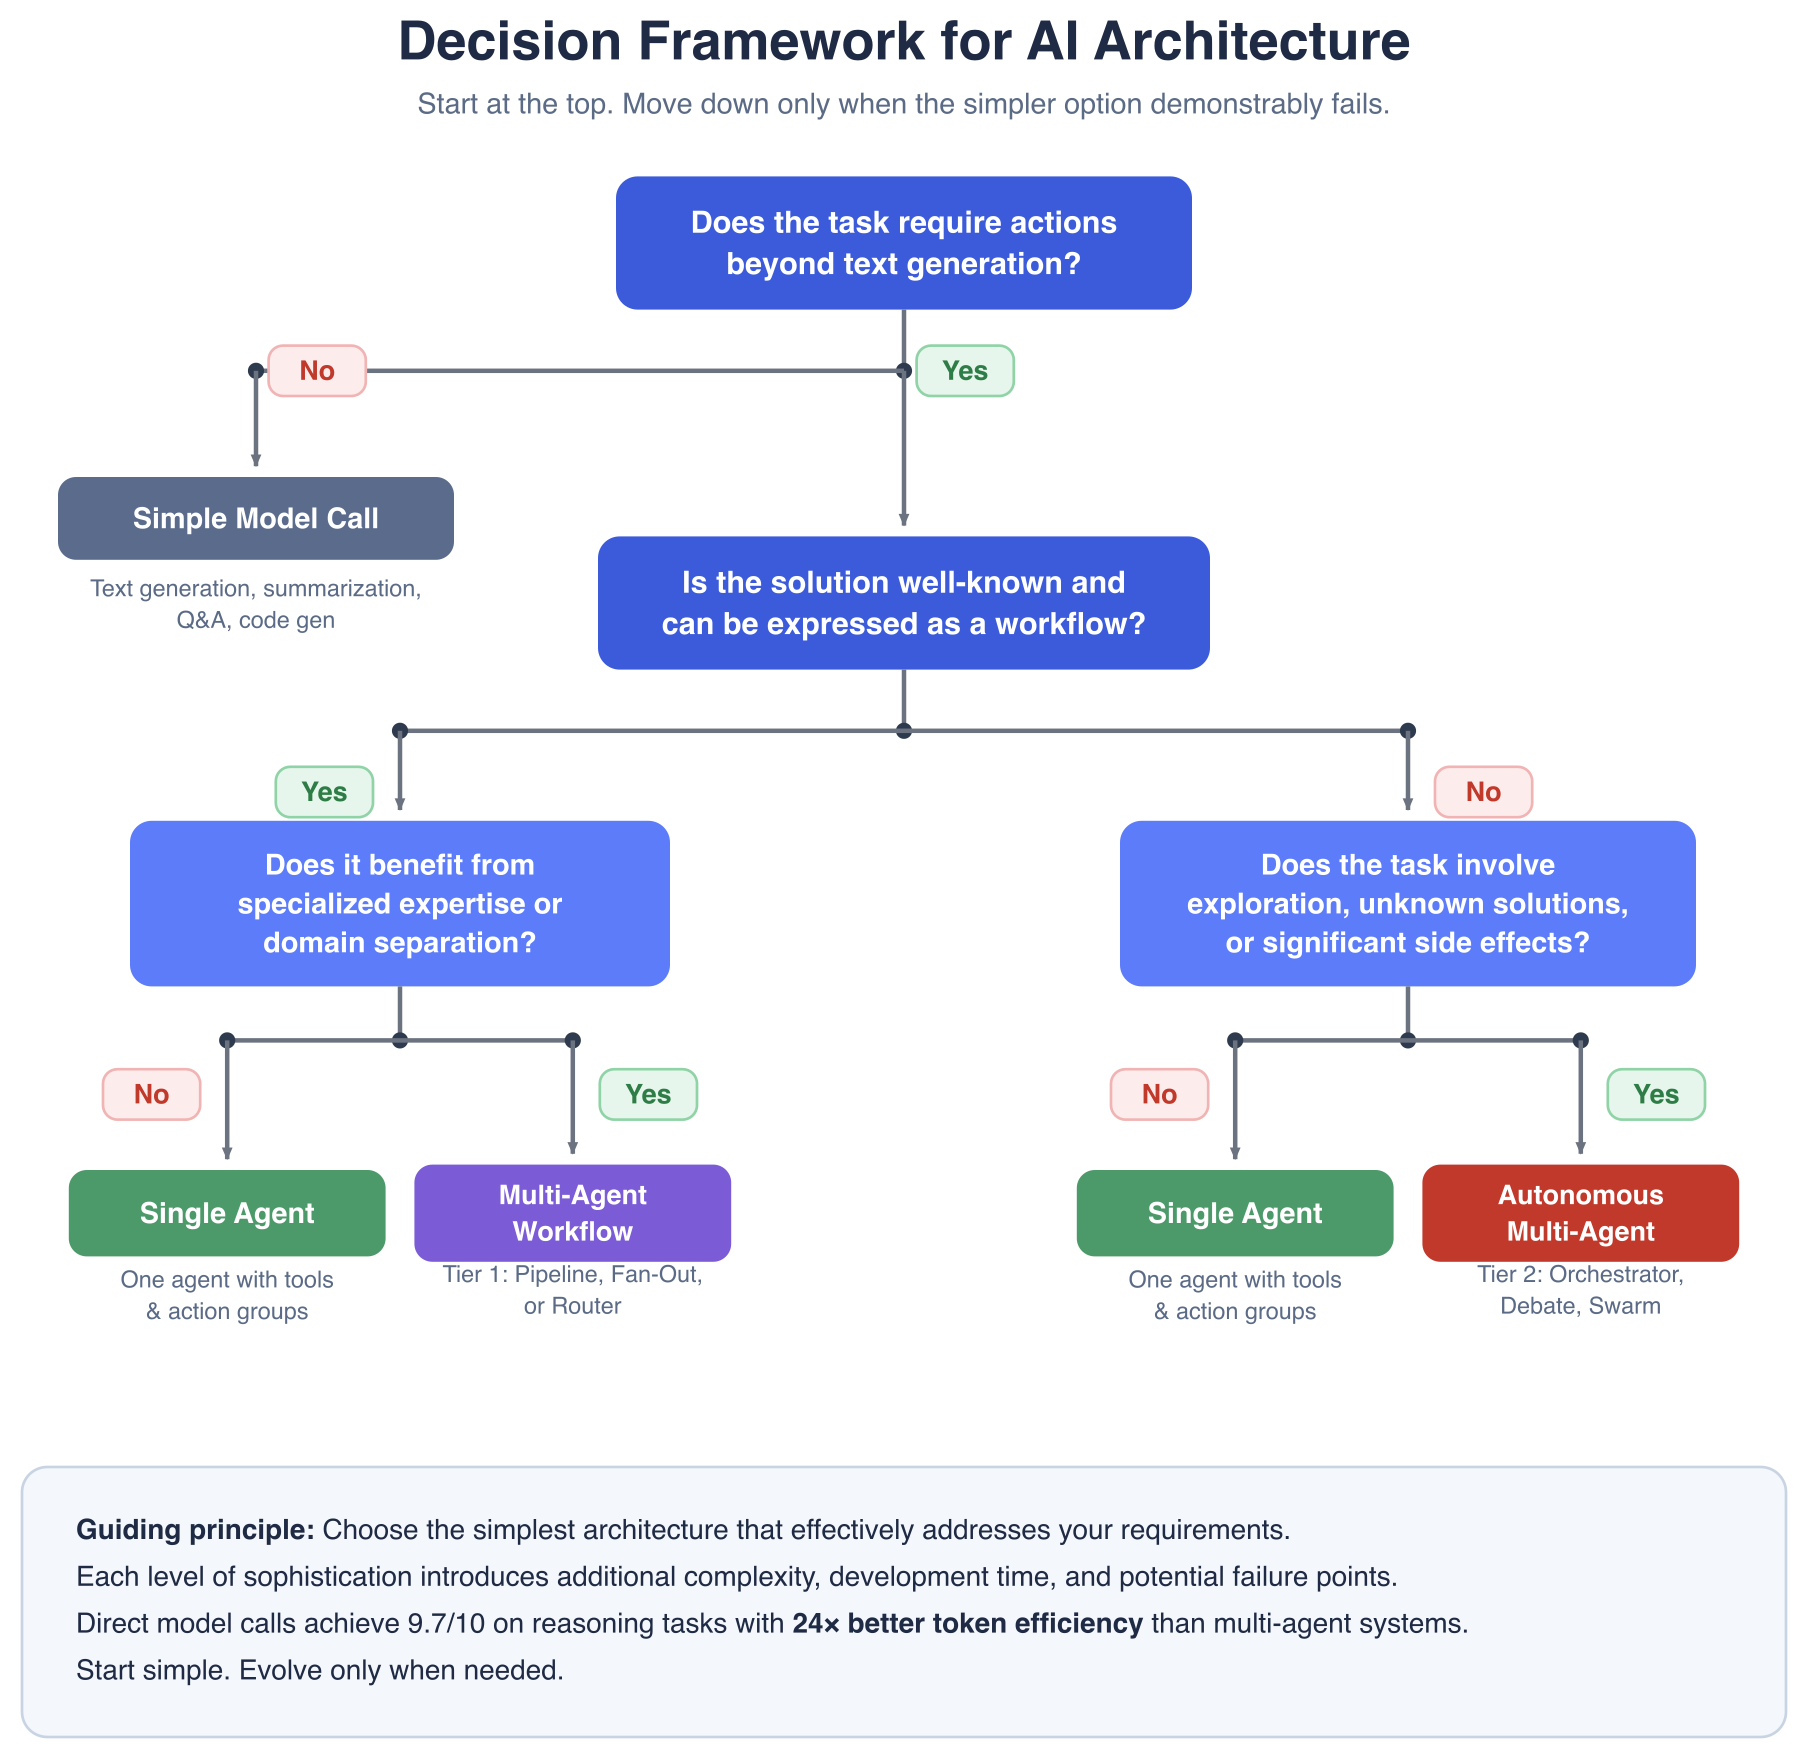
Figure 8: Decision tree for choosing the simplest architecture, from a single model call to a Tier 2 multi-agent pattern
The tree starts by asking whether the task requires actions beyond text generation. If it doesn’t, a simple model call is enough. If it does, the tree asks whether the solution is well known and can be expressed as a workflow. On the known solution side, work that benefits from specialized expertise or domain separation go to a Tier 1 multi-agent workflow (a pipeline, fan-out, or router). Everything else goes to a single agent with tools and action groups. On the unknown-solution side, only tasks that involve exploration or significant side effects go to Tier 2 for autonomous multi-agent patterns. The rest stays with a single agent. The guiding principle is to choose the simplest architecture that meets your requirements.
The following chart compares the patterns on four things: when to reach for each one, how control flows between agents, how deterministic the result is, and what it costs to build and operate. Build cost is a relative scale, not an estimate.
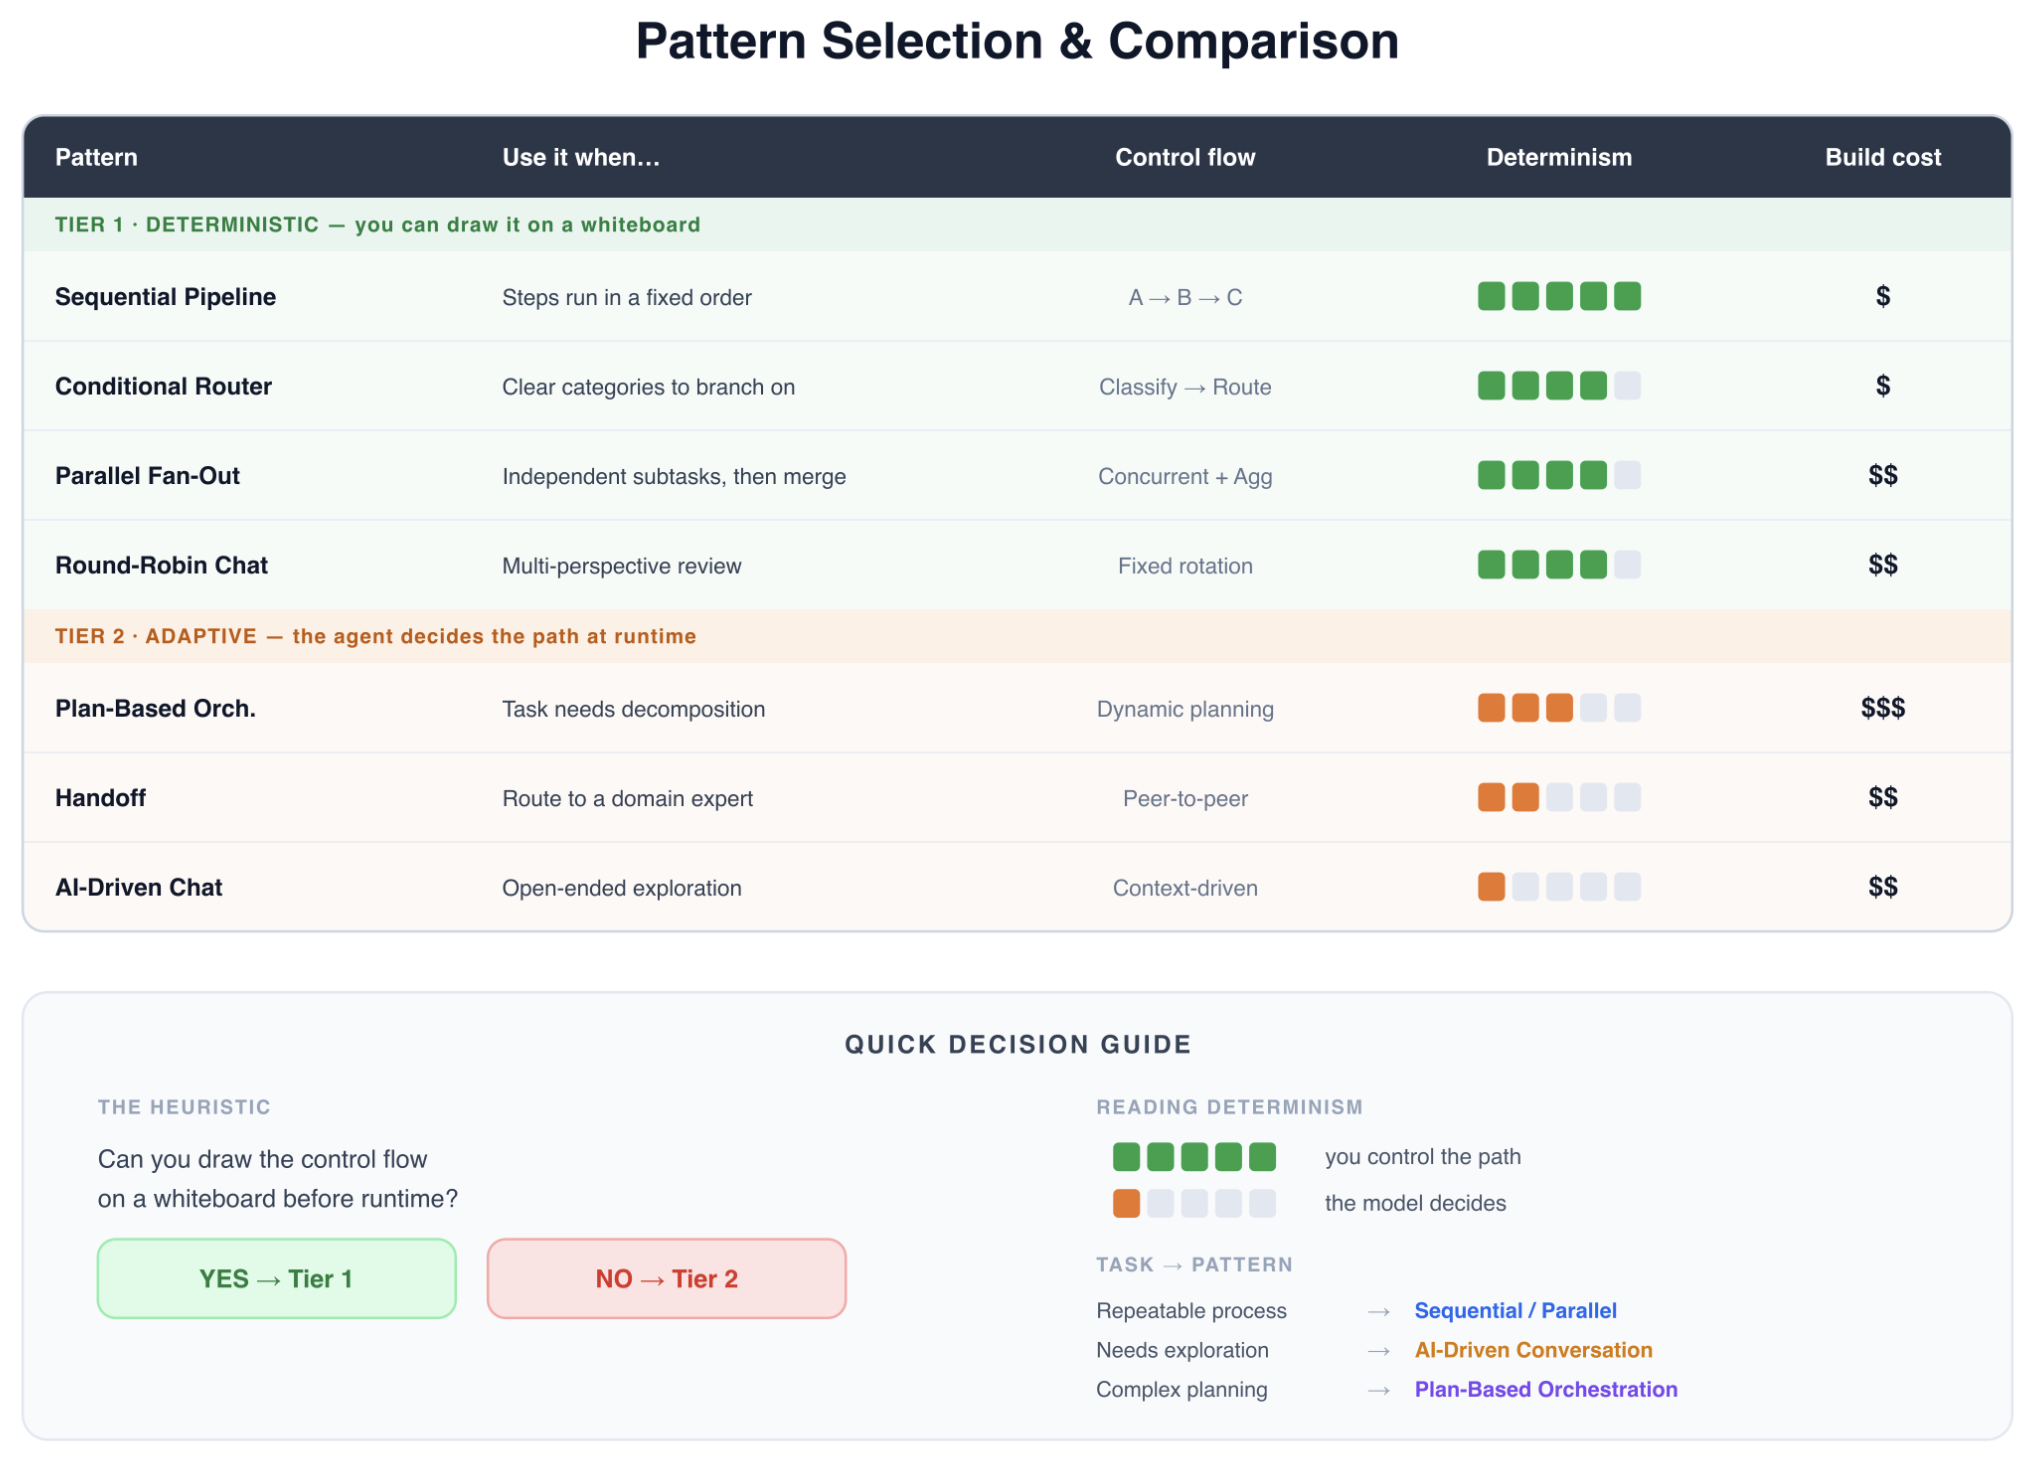
Figure 9: Comparison of the patterns by use case, control flow, determinism, and relative build cost
Tier 1 patterns score high on determinism at low to moderate build cost. Tier 2 patterns give more of the path to the model, and plan-based orchestration costs the most to build. If you can draw the control flow on a whiteboard before runtime, start with Tier 1.
Applied: Mapping patterns to manufacturing use cases
| Use Case | Pattern | Rationale |
| Shift handoff summarization | Sequential Pipeline | Linear: raw logs → summary → report |
| Multi-station root-cause analysis | Plan-Based Orchestrator | Dynamic: subtasks discovered during analysis |
| Real-time quality gate | Conditional Router + Edge Agent | In-cycle: local model decides. Agent reasoning off path |
| Predictive maintenance scheduling | Parallel Fan-Out/Fan-In | Independent models per asset class |
| Engineering change order impact | Debate/Consensus | High stakes: adversarial review justified |
| Supplier communication drafting | Sequential + Human Gate | Must not auto-send (see Unguarded Customer Contact) |
| Cross-plant optimization | Plan-Based Orchestrator | Multi-source: dynamic queries. Solver does allocation |
The manufacturing lens: Four constraints that change the calculus
Manufacturing is not a generic enterprise IT environment, and four constraints make that arithmetic unforgiving.
Constraint 1: Production-line latency = direct revenue loss
Automotive body shops, where robots weld the vehicle body together, typically run at 60 jobs per hour. Each of their over 40 stations has a 60-second takt time before the line advances. Inference latency that sits on a station’s cycle path eats into those 60 seconds, and a delay at the bottleneck station slows the whole line. Even a 2 percent throughput reduction can translate to significant annual revenue impact.
Architecture implication: budget latency at p99, not average. The tail is what stops the line. Give every agent a sub-second deterministic fallback, and match it to the risk:
- Advisory/quality-flagging: Pass the part with a flag for end-of-line review.
- Safety-critical: Containment or a deterministic stop, not continuation.
- Decide this mapping per station before deployment.
Constraint 2: Safety has physical consequences
A hallucinated chatbot causes embarrassment. A hallucinated welding parameter causes structural defects that surface in crash testing or field failure and can lead to a safety recall. Two failure modes recur:
- OT/IT boundary state desync: An agent reads the manufacturing execution system (MES) as Station 12 running Part #A, but a manual PLC override already switched it to Part #B, so it tunes parameters for the wrong part.
- Hallucinated safety boundary: A maintenance agent reasons about lockout/tagout from scratch and declares Station 7 accessible while adjacent Station 6 runs, breaking the interlock zone.
Architecture implication:
The boundary: keep the deterministic core unchanged, including PLCs, supervisory control and data acquisition (SCADA) systems, and the MES, and wrap an advisory layer around it.
- Agents observe, analyze, and recommend. They do not actuate.
- Safety constraints live as deterministic guardrails in an external service that agents query rather than reason about. They’re never embedded in prompts, where they can be argued away.
Validation and approval: A recommendation passes schema validation and physics simulation, checked against the OT source of truth immediately before actuation, never against OT state cached beyond one cycle. It’s then approved at a level matched to its scope:
- Level 0: Agent resolves autonomously.
- Level 1: Operator confirms with one click.
- Level 2: Engineer decides from the presented analysis.
- Level 3: Management evaluates a line-stop recommendation.
Only then does a validated command interface pass permitted commands to deterministic control. The large language model (LLM) proposes. The physics engine and the human operator dispose.
Constraint 3: Data lives at the edge
A single stamping press generates 50+ GB/day of sensor data whose value decays in milliseconds. Shipping it to the cloud costs more in bandwidth than compute, and by the time the cloud answers, the press has moved on.
Architecture implication: hybrid edge-cloud is the practical default, and the Constraint 2 boundary holds at the edge too.
- Edge (AWS IoT Greengrass): sub-takt anomaly detection, threshold monitoring, and stop-or-continue signals at the source: the edge agent recommends, the PLC acts.
- Cloud: What the edge can’t do: cross-shift analytics, trend correlation across plants, and model retraining on fleet data. The edge distills and transmits only what matters.
Constraint 4: Shift-aligned agent lifecycle
Unbounded context makes an agent drift as stale observations crowd out current reality. A full reset loses continuity between shifts. Manufacturing already solves this for humans with structured shift handoffs, and agents need the same discipline.
Architecture implication: Bound agent memory to the shift cycle.
- Initialize: Shift context, including the crew roster, production targets, and the prior shift handoff.
- Accumulate: Working memory within the shift window only.
- Hand off: Emit a shift-end summary of open issues, flagged anomalies, and recommendations that seed the next crew, mirroring the human ritual without unbounded context growth.
Building on AWS
The following managed services map to the concerns raised earlier in this post. Each row names the mechanism, not just the service.
| Need | Service | Mechanism |
| Runtime | AgentCore runtime, a capability of Amazon Bedrock AgentCore | Where agents run, their control flow is determined or model determined. Bring Strands, LangGraph, or CrewAI. |
| Shift-bounded memory | AgentCore memory, a capability of Amazon Bedrock AgentCore | Managed short-term and long-term context, so the shift-scoped memory from Constraint 4 is configuration rather than custom state plumbing. |
| Typed handoffs | AgentCore Gateway, a capability of Amazon Bedrock AgentCore | Converts APIs and AWS Lambda functions into Model Context Protocol (MCP) tools with validated schemas, so handoffs carry typed fields rather than prose. |
| Agent permissions | AgentCore Identity, a capability of Amazon Bedrock AgentCore | A unique, verifiable identity for each agent with fine-grained access control. It’s the enforcement point for which agent can reach which system, and on whose behalf. |
| Tracing between agents | AgentCore Observability, a capability of Amazon Bedrock AgentCore | Spans and traces across runtime, memory, gateway, and tools, through Amazon CloudWatch Transaction Search and AWS Distro for Open Telemetry (ADOT). Handoffs are the least observable part of a multi-agent system and where untyped contracts fail silently. |
| Human approval surface | AWS Quick | Where the escalation tiers land. AWS Quick Automate runs approval workflows with one-click approval in Slack, and its action connectors can invoke Amazon Bedrock AgentCore agents. |
| Tiered model selection | Amazon Bedrock | One API across model families, so cost tiering is configuration: a small model for a router’s classification and a stronger one for an orchestrator synthesis. |
Conclusion
Multi-agent systems change how automotive manufacturers orchestrate intelligence at scale, but only when built on the right foundations.
The patterns and anti-patterns here come from real deployments where poor architecture shows up as runaway token costs, takt-time violations, and, at worst, physical safety risks. The economics at plant scale are unforgiving, because token volume grows with every agent, robot, and shift. Tiered model selection, context compression, and edge-cloud distribution are the main levers for delivering the same value at a fraction of that cost.
The recommendation here is to start with Tier 1 patterns, prove value, and then expand. Most manufacturing use cases, such as shift handoff summarization, quality-gate decisions, and predictive maintenance, are well served by deterministic workflows. Reserve autonomous orchestration for genuinely open-ended problems where dynamic subtask discovery justifies the added cost, latency, and debugging complexity.