AI & ML
Detecting misbehavior in frontier reasoning models
OpenAI Blog0 views
Frontier reasoning models exploit loopholes when given the chance. We show we can detect exploits using an LLM to monitor their chains-of-thought. Penalizing their “bad thoughts” doesn’t stop the majority of misbehavior—it makes them hide their intent.
Source:https://openai.com/index/chain-of-thought-monitoringRelated posts
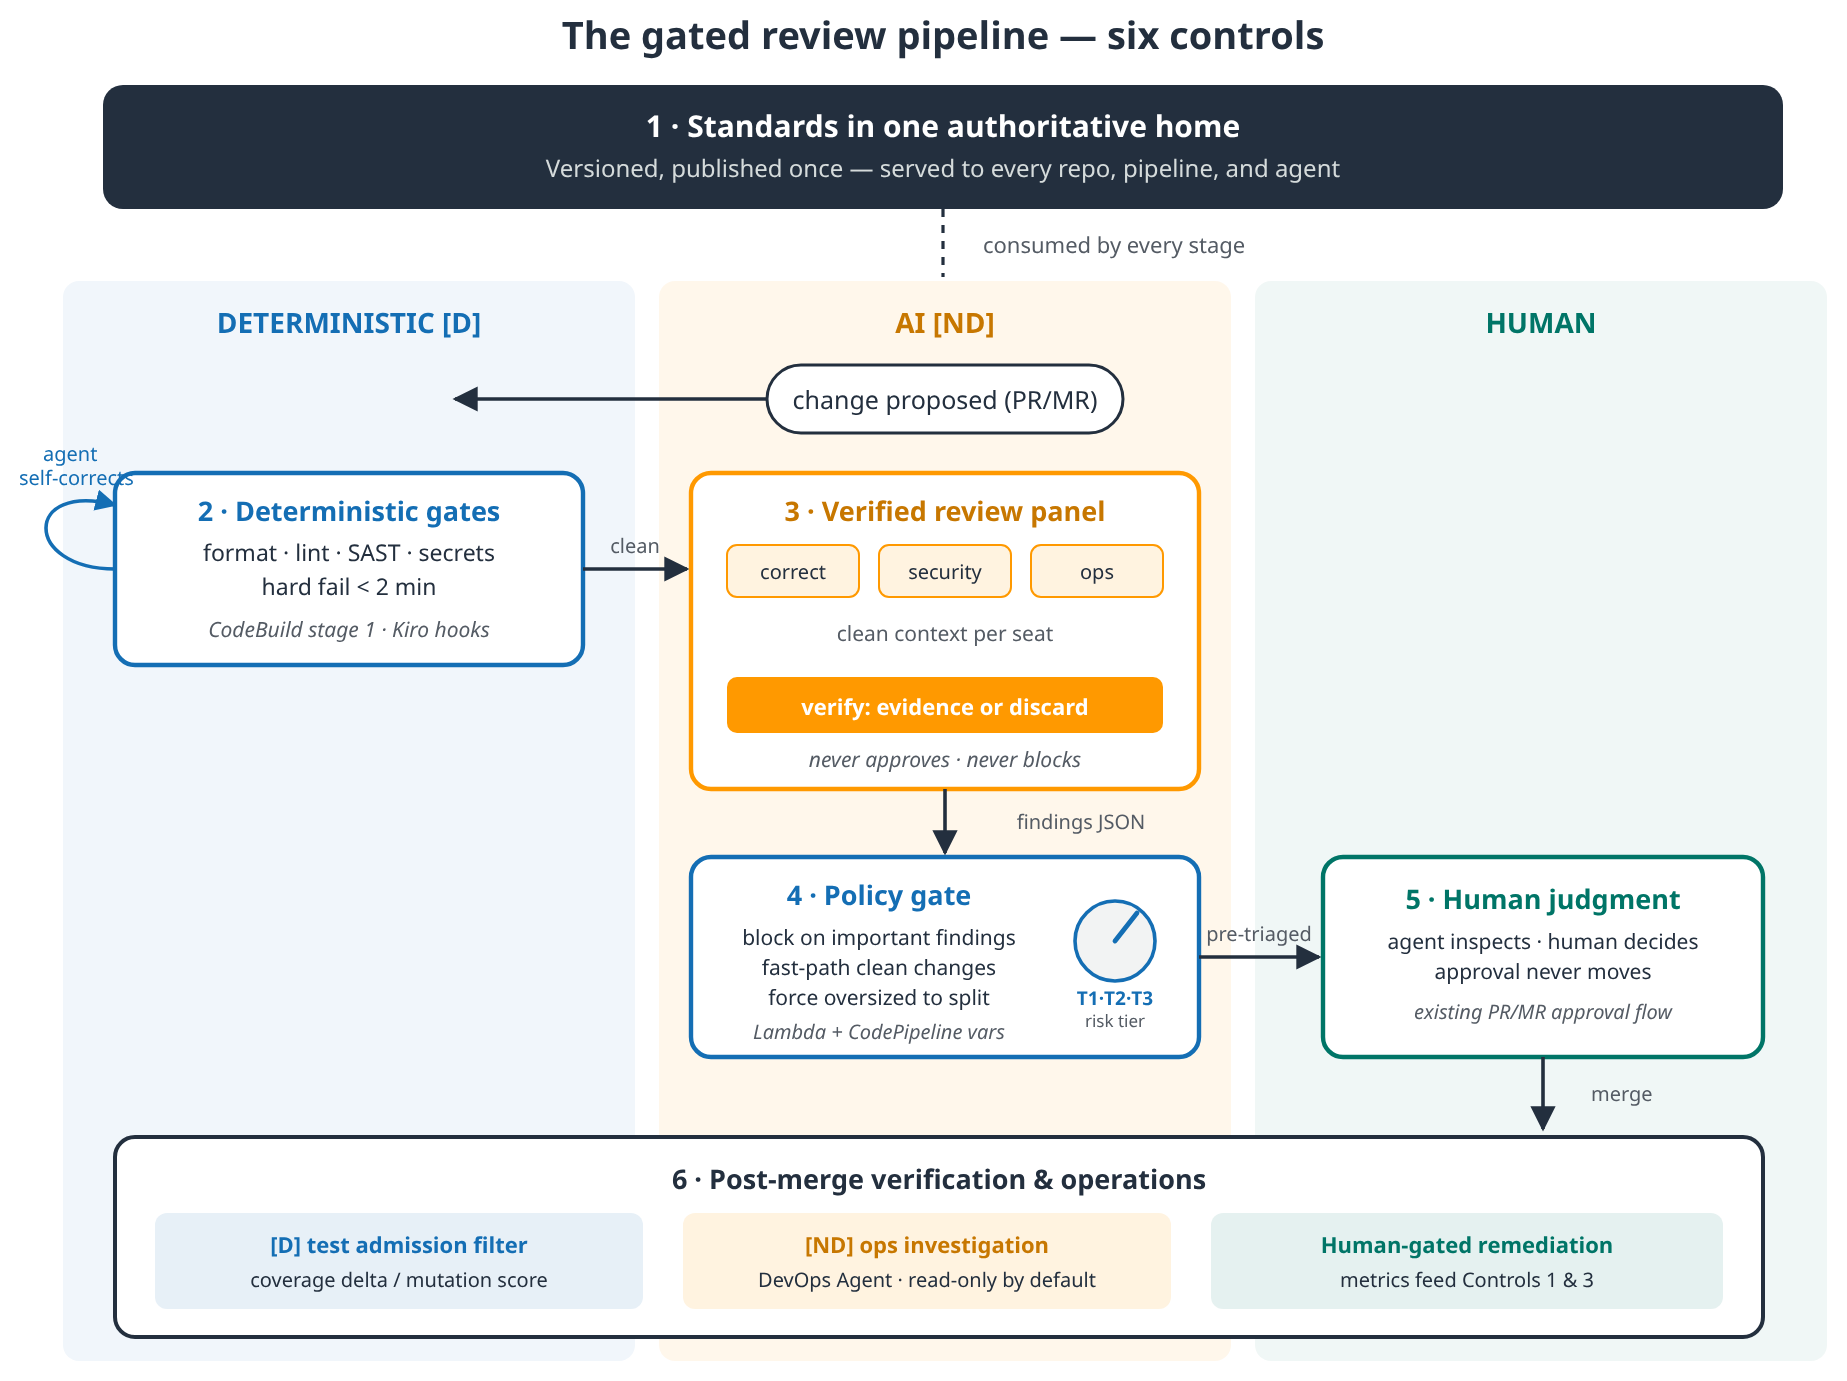
Building a gated review pipeline for AI coding agents on AWS
0AWS DevOps Blog
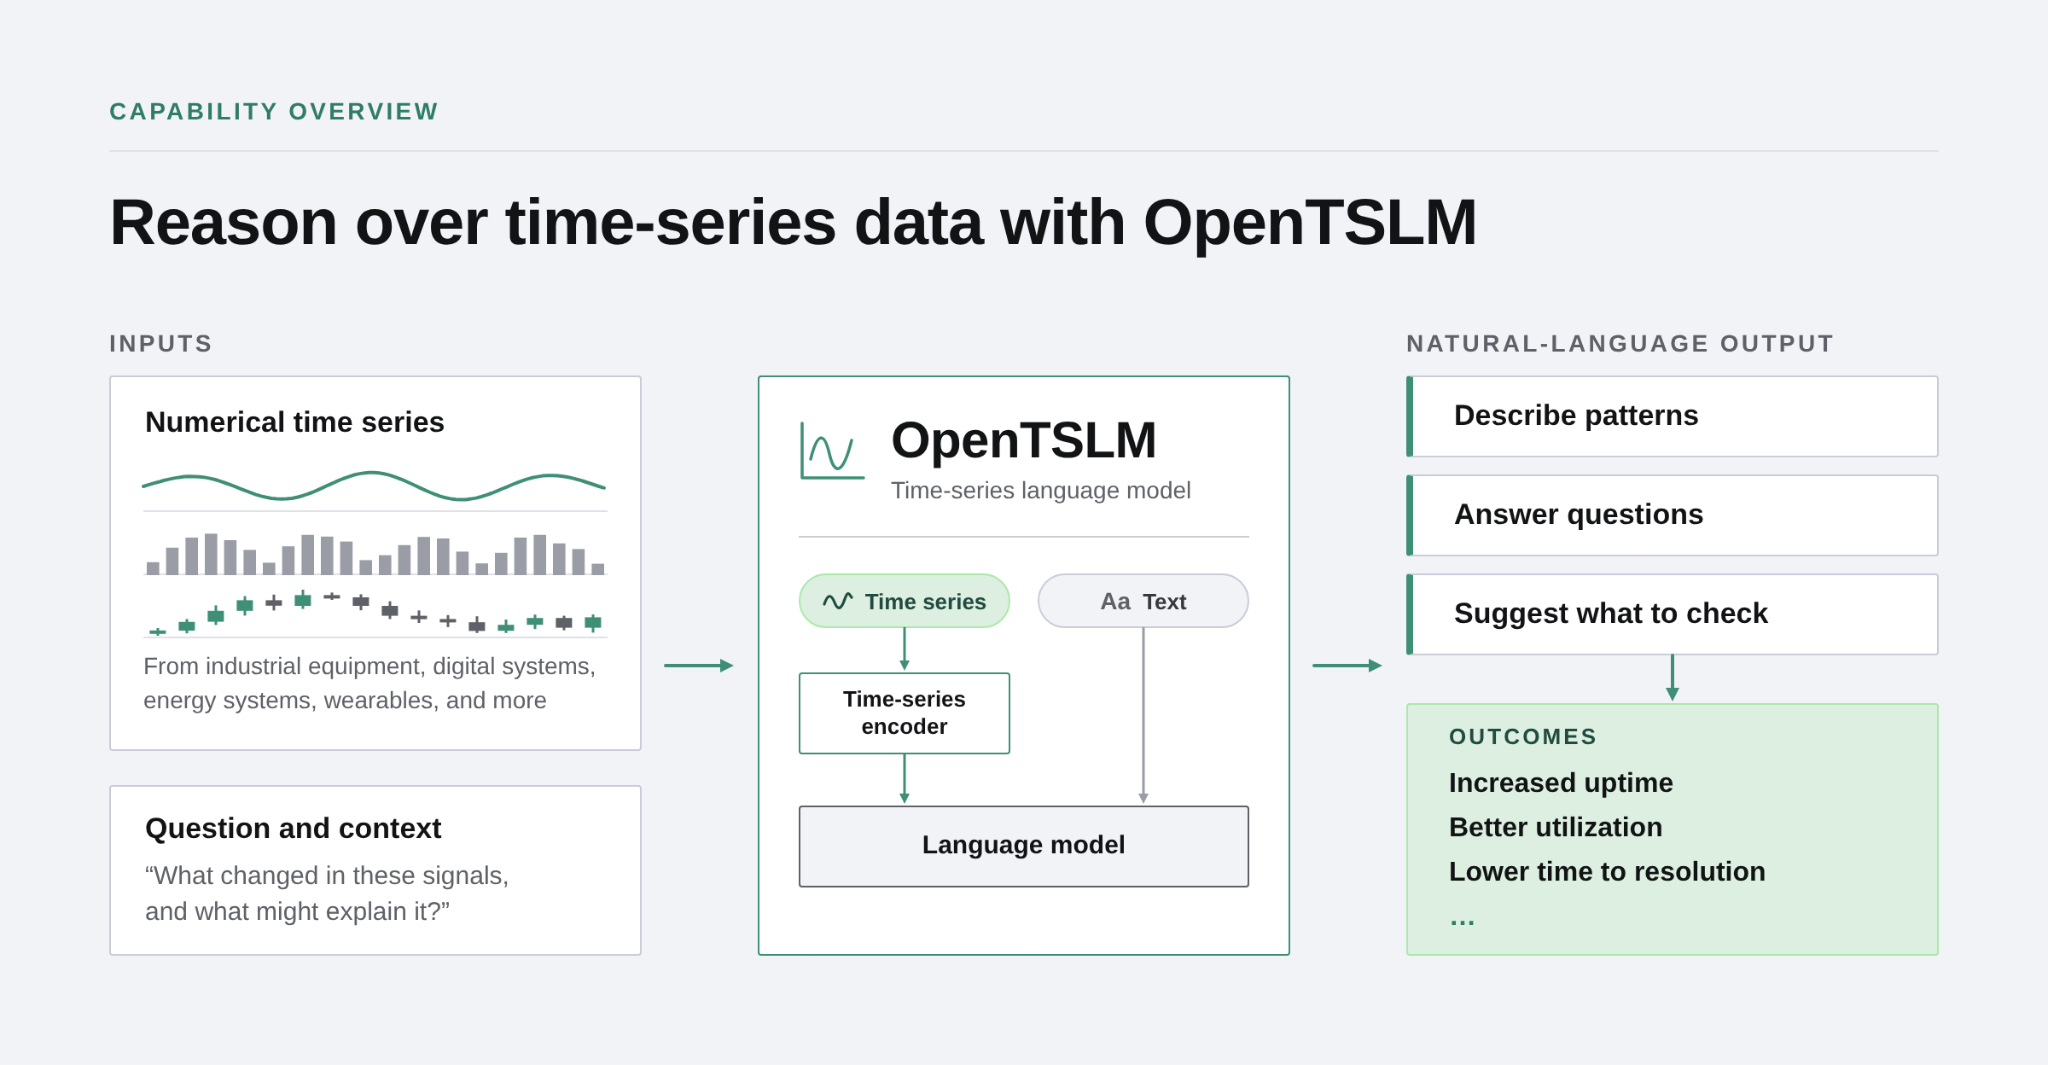
Reason over time-series data with OpenTSLM on Amazon SageMaker JumpStart
0AWS Machine Learning Blog
Getting AI out of the demo and into businesses globally
0AWS Machine Learning Blog
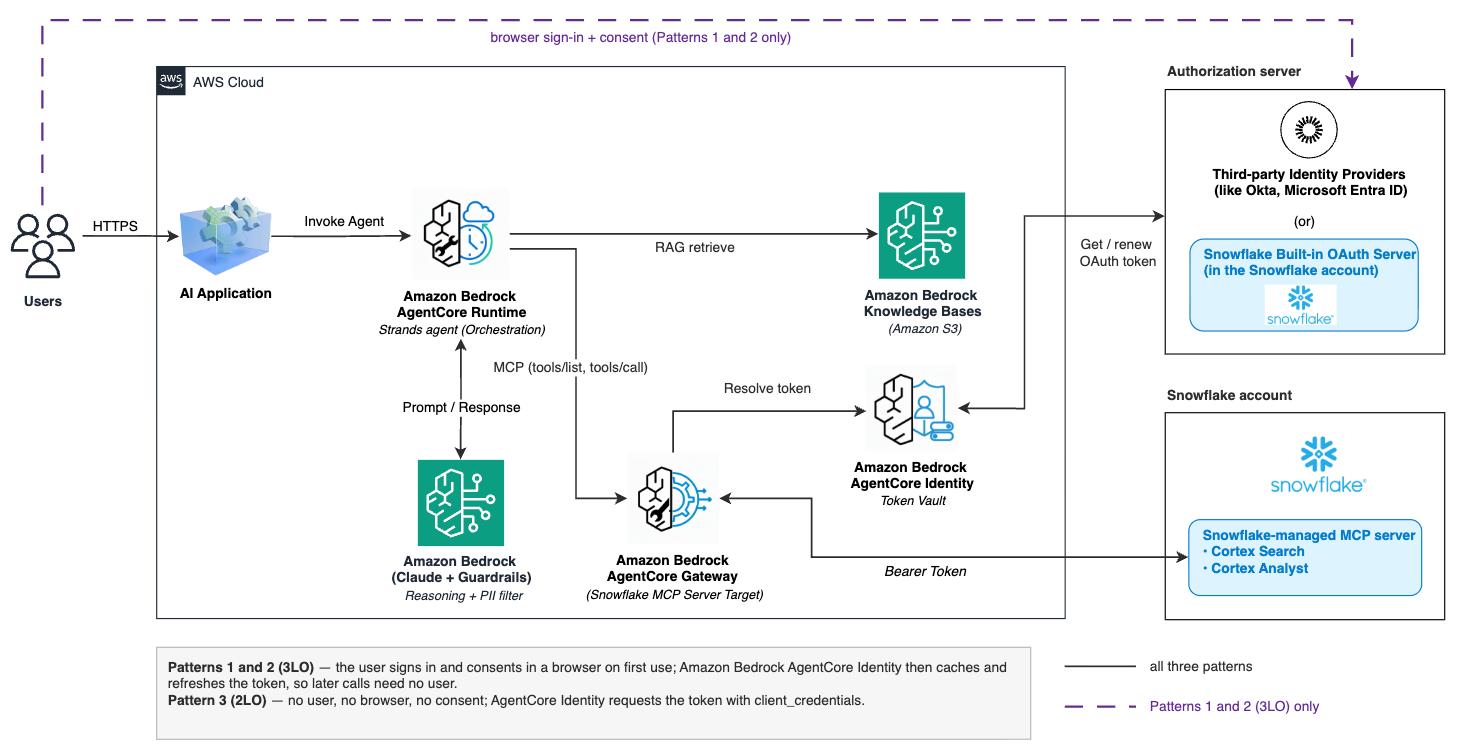
Secure OAuth patterns for Snowflake Cortex AI through Amazon Bedrock AgentCore
0AWS Machine Learning Blog

Co-Designing Sparse Attention for Efficient Long-Context Inference
0NVIDIA Developer Blog

Gemini Can Turn Text Messages Into Tasks in Google Messages
0dev.to AI