At Exa, we are building one of the few true web indexes by aggregating and serving knowledge from across the web, along with private and synthetic sources. We optimize the index for semantic search, grounding agents and humans in true, high-quality data. We use multi-tower semantic machine learning (ML) models to embed web data and query data into the same vector space, so users can express complex queries in natural language alongside traditional keyword search. The keystone technology behind this is an in-house vector database. It must ingest as much high-quality web data as possible and embed all of it. The unit economics of embedding therefore underlie everything we do. At the scale of tens or hundreds of billions of documents, finding the hardware that delivers the best performance per dollar isn’t a tuning detail. Any per-document cost improvement compounds into a significant number.
This post details how we optimized our embedding infrastructure for cheaper, more flexible inference workloads on AWS Neuron hardware (AWS Inferentia2 and AWS Trainium2), and how an agentic development workflow drove the optimization.
Inference runs on an asynchronous pipeline, but it must be high-volume and fast to serve recent data quickly and shrink the time between discovery and serving.
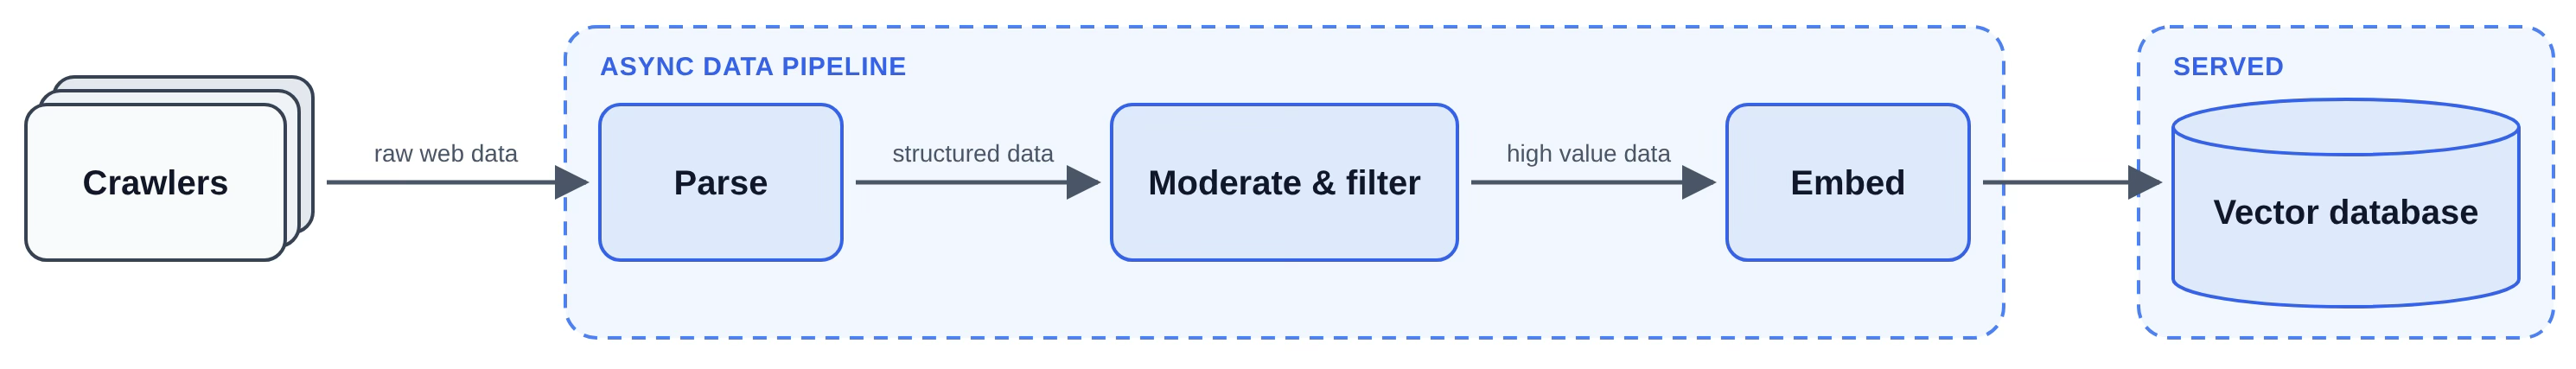
Figure 1: A simplified view of the Exa stack
Every structured web document we rank as high enough quality must be embedded before it can be served. This figure shows how raw web data moves from Crawlers into an asynchronous pipeline of Parse, Moderate and filter, then Embed, with the result served from a vector database.
Embedding documents at scale
Our experience with the Neuron hardware family began with a backfill. Moving to a superior document model meant re-embedding our existing corpus. We selected 30 billion high-priority documents for re-embedding. A migration like this temporarily doubles the embedding load, which made it exactly the right moment to re-evaluate our hardware choices.
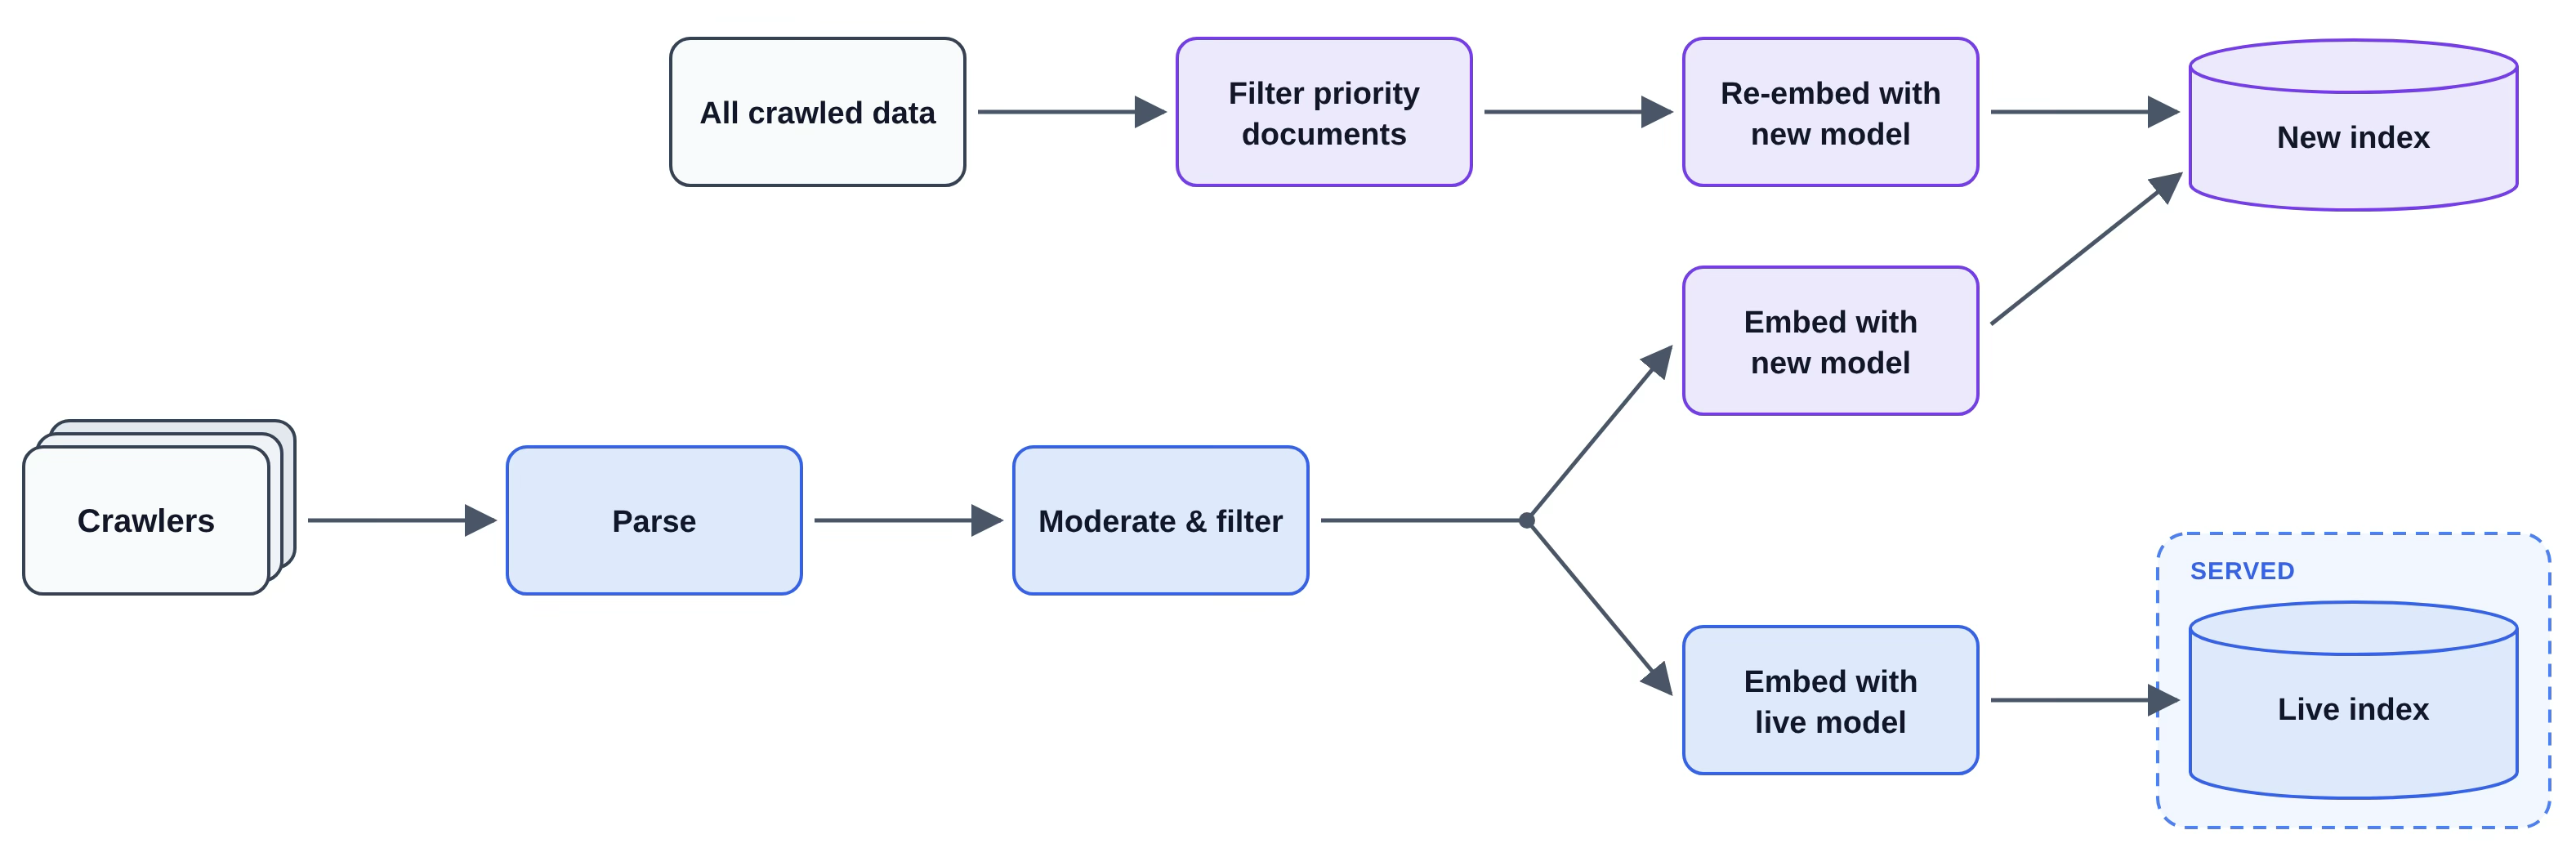
Figure 2: The doubled inference load from the backfill
The preceding figure shows two parallel pipelines sharing the crawl and parse stages, one embedding with the live model into the live index and one re-embedding priority documents with the new model into the new index, which is what doubles the load. This doubling was a clear trigger to reconsider our hardware and optimization choices.
Optimization journey
AWS Inferentia2 figures refer to performance on the smallest instance type, an Inferentia2 xlarge instance (inf2.xlarge), with one chip and two NeuronCores. Our workload runs on a single NeuronCore, so we run Kubernetes pods that pack onto larger instances without leaving any cores idle, giving us container homogeneity across the embedding fleet. The same process runs on a Trainium2 NeuronCore and scales the same way through data parallelism. Our initial Inferentia2 implementation was a straightforward data-parallel, FP16 representation of the model. From that baseline, it became a march to push throughput (docs/sec) as high as possible, using the Neuron SDK and support from the AWS Trainium team. The following chart shows the throughput gains at each milestone.
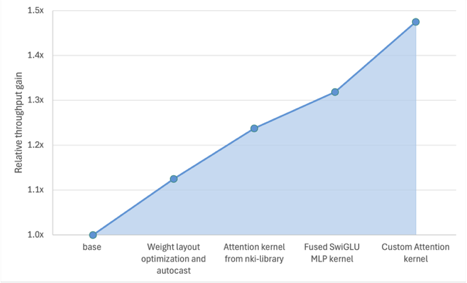
Figure 3: Throughput improvement across optimization milestones
Starting from the naive compile, a progressive series of optimizations ultimately delivered roughly a 1.5× throughput improvement. The first was weight layout optimization, which eliminates unnecessary transposes by aligning the weight layout with the scheduling and layout of the broader model. We also enabled autocast, letting the compiler downcast matrix multiplications to lower precision while preserving dynamic range. The downcast outputs met our correctness gate of 0.999 cosine similarity against the reference (see Agentic methodology), so the accuracy impact was within our acceptance threshold.
NKI kernels
The Neuron Kernel Interface (NKI) library provides optimized kernels for common model layers and operations. These pre-built kernels deliver immediate gains on common features, and we used them to quickly remove the most straightforward sources of inefficiency. A drop-in attention kernel gave us the next bump in performance.
Memory layout optimization: A fused SwiGLU MLP kernel
The next bottleneck was memory spill. Profiles from the Neuron Explorer consistently showed large amounts of spill and reload from high-bandwidth memory (HBM), which kept the Tensor Engine from being fully utilized through the forward pass. Using a drop-in MLP kernel as a steppingstone to profile the shortcomings of the pre-built implementation, we wrote a custom weight-stationary fused SwiGLU MLP kernel that eliminated the HBM stalls.
We used the higher-level NKI language for layout operations, loops, and memory operations, and only dropped into the lower-level NKI ISA for specific tensor operations. Keeping most of the kernel in the higher-level language makes it more understandable for engineers, and easier to debug.
FLOPS reduction
At this point we hit a wall. Per-accelerator throughput measured with the other on-chip core idle was significantly higher than what we saw with both cores running simultaneously. That gap meant our theoretical data-parallel throughput should have been well above our realized aggregate performance, which pointed to contention between the cores.
Profiling and experimentation showed that our workload wasn’t yet saturating the Tensor Engine. The remaining headroom was ours to claim by making the computation leaner. The clearest path left was to reduce the overall FLOPS needed to produce our results by eliminating waste. We rewrote the attention kernel around the exact shapes in our model to cut FLOPS spent on padding. This is where kernel customization really paid off. Generic kernels are built to handle any shape, so they can’t take advantage of the specific shapes in a given architecture. We wrung more performance out of attention by tailoring the implementation to the real shape of our model’s head architecture. We also folded attention operations into single matmuls where the generic kernel used multiple instruction steps. That cut the inner-loop operations needed to compute the same values, which reduced HBM round trips and produced the final significant speedup.
In total, our final version was a 47% improvement in performance and cost per 1 million documents embedded, against our initial baseline.
Agentic methodology
Agents developed all of these optimizations inside a simple three part harness that lets them verify correctness, measure performance and profile the workload to find the next direction. Using Flyte, an ML ops workflow platform, each agent runs its own workflow. The workflow compiles a NEFF Neuron executable and checks a forward pass against a baseline dataset, which must reach 0.999 cosine similarity to the canonical model. It then profiles one forward pass and runs a 30 minute saturation benchmark on real hardware.
The harness supports agents at different costs. Lightweight models handle tedious work like grid searching compiler parameters, and correctness checks prevent drift. Reasoning agents test complex hypotheses and find bottlenecks, while the strongest code generators write custom kernels to fix them. Matching each agent to its task keeps costs in check, and validation keeps capable agents from drifting. Because many agents don’t know the latest features and syntax, neuron agentic development skills also helped.
The benefits of flexible compute
So far, we have optimized Inferentia2 for the US West (Oregon) Region (us-west-2), but tuning one hardware family in one Region has hard limits. Spot and on demand availability vary by Region, and organizations with many consumers compete with themselves. Locking into one Region or instance type almost guarantees a compute shortage, and possibly degraded service.
Exa schedules compute across multiple Regions from one Kubernetes control plane. Our scheduler compares performance per dollar across instance types and packs pods onto the cheapest nodes, rescheduling as embedding demand shifts. Each hardware type we optimize for brings us closer to the global optimum. This is why our Inferentia2 work carried over directly to Trainium2. Shifting hardware profiles lets us free up nodes other teams need or absorb their unused reserved compute. For a long lived model, optimizing across hardware pays off enormously.
Conclusion
At the scale Exa operates, extracting maximum cost-performance from a flexible pool of hardware is what matters. Adding Neuron hardware to that pool and optimizing it with NKI has proven to be a major source of long-term cost savings.


