A Pat Gelsinger-backed Georgia Tech spinout, Nagare Labs, says its Z2RAM can put SRAM-speed memory, at DRAM density, directly on top of AI chips. The founders’ own papers show a fast-improving cell that, tested up to 85 degrees Celsius, holds data for over 300 seconds. Gen 1 is projected to have 5x SRAM density with six stacked layers, 14x DRAM speed, and 3x less read energy than SRAM.
AI chips require a lot of bandwidth, and it has been challenging to get sufficient yields of high-bandwidth memory (HBM) to feed them. Even when manufacturers can get it, some reportedly plan to settle for fewer layers for yield reasons, and heat is another. Heat is also why Samsung’s zHBM, which stacks DRAM directly on the processor, is planned at only about four layers.
Alternatives include high-bandwidth flash, still in development, which stacks NAND like HBM and would sit beside the GPU, or SRAM stacked directly on the die, which is less dense and more expensive for the capacity, but also faster. DRAM, which is more capacious, can sit on top of the compute, but heat limits how hard the logic underneath can run.
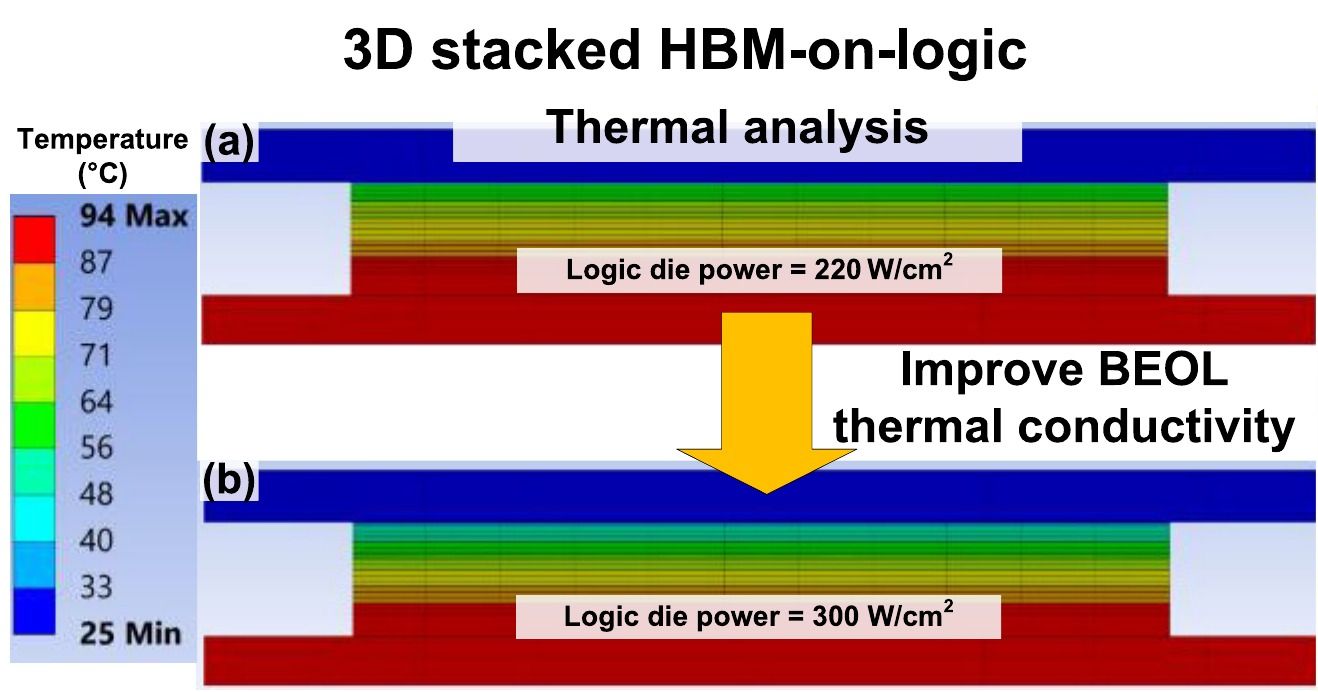
That limit is already shaping chipmakers’ design path for stacked memory. Micron’s vHBM plans, for example, include heat-spreading structures. With HBM stacked on a logic die, and DRAM needing to be kept at or below 95 degrees Celsius, the logic’s heat output is capped at 220 W/cm², or 300 W/cm² with better thermal vias, according to a 2025 simulation by co-founder Shimeng Yu’s group. Nagare Labs says peak compute has grown 70% a year over the past three decades, against 20% for memory bandwidth.
The company describes its Z2RAM as “Two transistors and a shield. No capacitor,” where a write transistor places a charge on a storage node and the shield blocks noisy neighbors. The read transistor can sense without draining. In a gain cell like this, the read transistor’s gate capacitance holds the charge, so reads are non-destructive and the cell avoids DRAM’s write-back. Nagare aims for well under a picojoule per bit.
Nagare builds Z2RAM by depositing its layers on top of the accelerator and patterning them “together on one die,” much as 3D NAND flash scales by adding layers. There’s no interposer and no bonds between the memory layers, which is part of the secret sauce. One lithography exposure covers several layers at once, and standard 300 mm tools with DUV do the job, with no EUV required. The current roadmap is aiming at over 100 layers with “hundreds of thousands” of vertical connections.
Retaining data at higher temperatures is the challenge, and one the founders have probed repeatedly with their testing. A 2020 paper from co-founder Suman Datta’s group, on a tungsten-doped indium oxide two-transistor cell, had retention of 1 second at 25 degrees Celsius and just 300 milliseconds at 85°C. An update in 2025, which has Datta as a co-author, adds a third transistor and removes the gate overlap from its transistors, managing over 1,000 seconds at 25°C, up from 200 seconds with overlapped ones. It also simulated a GPU L2 at twice SRAM’s capacity but in the same area with 75–80% lower energy-delay-area product, a combined score that multiplies energy, delay and area.
Six months later, both founders showed a “folded asymmetric boosted” three-transistor cell that held data for over 300 seconds at 85°C, as compared to only 100 milliseconds for a conventional three-transistor design. That’s still below the roughly 95°C that Nagare says DRAM must stay under, so neither the founders’ published cells nor Z2RAM have shown retention above that line yet. The boosted cell is also “refresh-free,” which means data in the GPU’s last-level cache, profiled from AI workloads, doesn’t have time to decay before it is overwritten.
Figure | Value | Measured, simulated or projected | Conditions | Source |
|---|---|---|---|---|
2020 two-transistor cell, retention | 1 s; 300 ms | Measured | 25°C; 85°C | Datta’s group, IEDM 2020 |
2025 three-transistor cell (self-aligned), retention | More than 1,000 s | Measured | 25°C | Georgia Tech, IEDM 2025 |
Conventional three-transistor cell, retention | 0.1 s | Measured | 85°C, to a 100 mV decay | Georgia Tech, VLSI 2026 |
Boosted three-transistor cell, retention | More than 300 s | Measured | 85°C, to a 100 mV decay | Georgia Tech, VLSI 2026 |
Write pulse | 10 ns | Measured | Two-transistor cell | Georgia Tech, IEDM 2025 |
Read delay | 2.6 ns | Simulated | 7nm design, 128×128 array | Georgia Tech, VLSI 2026 |
Cell area | 0.0168 µm² | Projected | 7nm design rules | Georgia Tech, VLSI 2026 |
Bit density | 5.7× that of 7nm SRAM | Simulated | Four tiers, 256MB, same area | Yu’s group, IEEE Trans. Computers 2026 |
GPU L2 energy-delay-area product | 75–80% lower than SRAM | Simulated | Twice the capacity in the same area | Georgia Tech, IEDM 2025 |
Logic power under stacked DRAM | 220 W/cm² (300 W/cm² with better thermal vias) | Simulated | DRAM kept at 95°C or below | Yu’s group, JxCDC 2025 |
Nagare Gen 1 density | 5× SRAM | Projected | Six layers, vs. 2nm HD SRAM | Nagare Labs |
Nagare Gen 1 speed | 14× faster than DRAM | Projected | Gen 1 | Nagare Labs |
Nagare Gen 1 read energy | 3× less than SRAM | Projected | Gen 1 | Nagare Labs |
Physical space is also limited for this application, and the founders project their boosted cell at 0.0168 µm² at 7nm, compared with 0.0199 µm² for a high-density SRAM cell on TSMC’s 3nm (N3) process. A separate study from Yu’s group found that a four-tier, 256MB cache of two-transistor gain cells at 7nm could reach 5.7x the bit density of 7nm SRAM in the same area, in simulation. However, the return on investment falls off past seven or eight tiers because masks scale with layers. Nagare Labs’ claim of single lithography would potentially bypass this limitation.
That has not yet been proven, and nothing published yet shows it. “Where we are is literally lab prototypes,” Datta told The Register, adding that sampling of Z2RAM tiles is targeted within four years and production shipments, if they arrive, within the next decade. Yu told the outlet that no standard yet exists for integrating this kind of memory with an accelerator, which means Nagare might have to come up with the interface itself. Datta also mentioned reliability to the outlet, as single-electron effects can shift a cell’s threshold enough to upset the stored bit. It also remains to be seen if the tested three-transistor cells work sufficiently well as a two-transistor, single-shield product.
Even if Nagare clears those hurdles, a more important one lingers: It currently has no fab. The plan to scale depends on getting partners for fabrication as well as packaging. Nagare is reportedly looking for an R&D fab partner so it can scale beyond the university clean room. Perhaps the most similar type of memory-on-compute shipping today, and the one Datta cited to the outlet as a model for working with chipmakers, is AMD’s 3D V-Cache.
Z2RAM isn’t the first capacitorless memory to promise a 5x improvement over SRAM in density; it follows in the footsteps of Innovative Silicon’s Z-RAM from 20 years ago, a technology AMD licensed, though it was not pursued. A Georgia Tech paper due at IEDM in December covers a different device, a one-transistor, one-ferroelectric-transistor cell, aimed at the same gap between SRAM latency and DRAM density.
Gelsinger, previously CEO of Intel, which started as a memory company, phased out Optane, a low-latency non-volatile memory, in favor of CXL. Optane sought to bridge the gap between slower non-volatile storage, such as HDDs and standard SSDs, and DRAM. Now he sits on Nagare’s board, and Playground Global, where he is a general partner, led the startup’s $5 million round as Nagare searches for a solution to a different but related problem.
Nagare declined to share measured retention, latency, or energy figures. The founders’ boosted cell already holds data at 85°C longer than a cache needs, but until a fab-built, multi-layer Z2RAM stack is measured, retention above 95°C included, its headline numbers remain projections.