AI & ML
OA-WAM: Object-Addressable World Action Model for Robust Robot Manipulation
arXiv cs.RO0 views
arXiv:2605.06481v2 Announce Type: replace Abstract: World action models (WAMs) learn manipulation by predicting actions and future observations, yet their success drops sharply when the camera viewpoint, object layout or robot initial state changes. Such changes keep the instructed object the same but alter the appearance and pose features the policy observes, which in standard attention also form the keys that locate the object. We introduce OA-WAM, an object-addressable WAM that finds each object by an identity address fixed for the episode and reads its changing state. In every layer of a pretrained multimodal trunk, object-slot keys depend only on the address and frame position, and values carry the current state; the same addresses key the action pointer and index per-object forecasts, which can trigger re-grounding. Fine-tuned on standard LIBERO demonstrations, OA-WAM transfers zero-shot to LIBERO-Plus with 90.5% success, outperforming all ten published baselines. It also leads on LIBERO (99.0%) and, fine-tuned on BridgeData V2, on SimplerEnv WidowX (88.9%). On five real-robot tasks, it succeeds in 89 of 100 nominal trials, versus 73 for the strongest baseline. Ablations trace its robustness to addressing rather than to object slots: with standard attention, slots do no better than a slot-free policy, and addressing them by identity raises geometric success by 10.7 points. Forecasting the addressed objects is likewise a stronger training signal than forecasting image codes.
Source:https://arxiv.org/abs/2605.06481PreviousI crawled 33,000 x402 payment-gated endpoints - here's what actually gets paidNextDSSP: Diffusion State Space Policy with Full-History Encoding
Related posts

How AUMOVIO centralized AI access with Databricks Unity Gateway
0Databricks Blog

What's new for Genie in Microsoft: Copilot Cowork and Chat, Microsoft Teams, and Excel.
0Databricks Blog

Introducing Unity Gateway Insights
0Databricks Blog
Shadow AI Is Shipped to You, One Release Note at a Time
0Imperva Blog
Our Approach to Updating Our Commercial Terms of Service
0Meta Newsroom
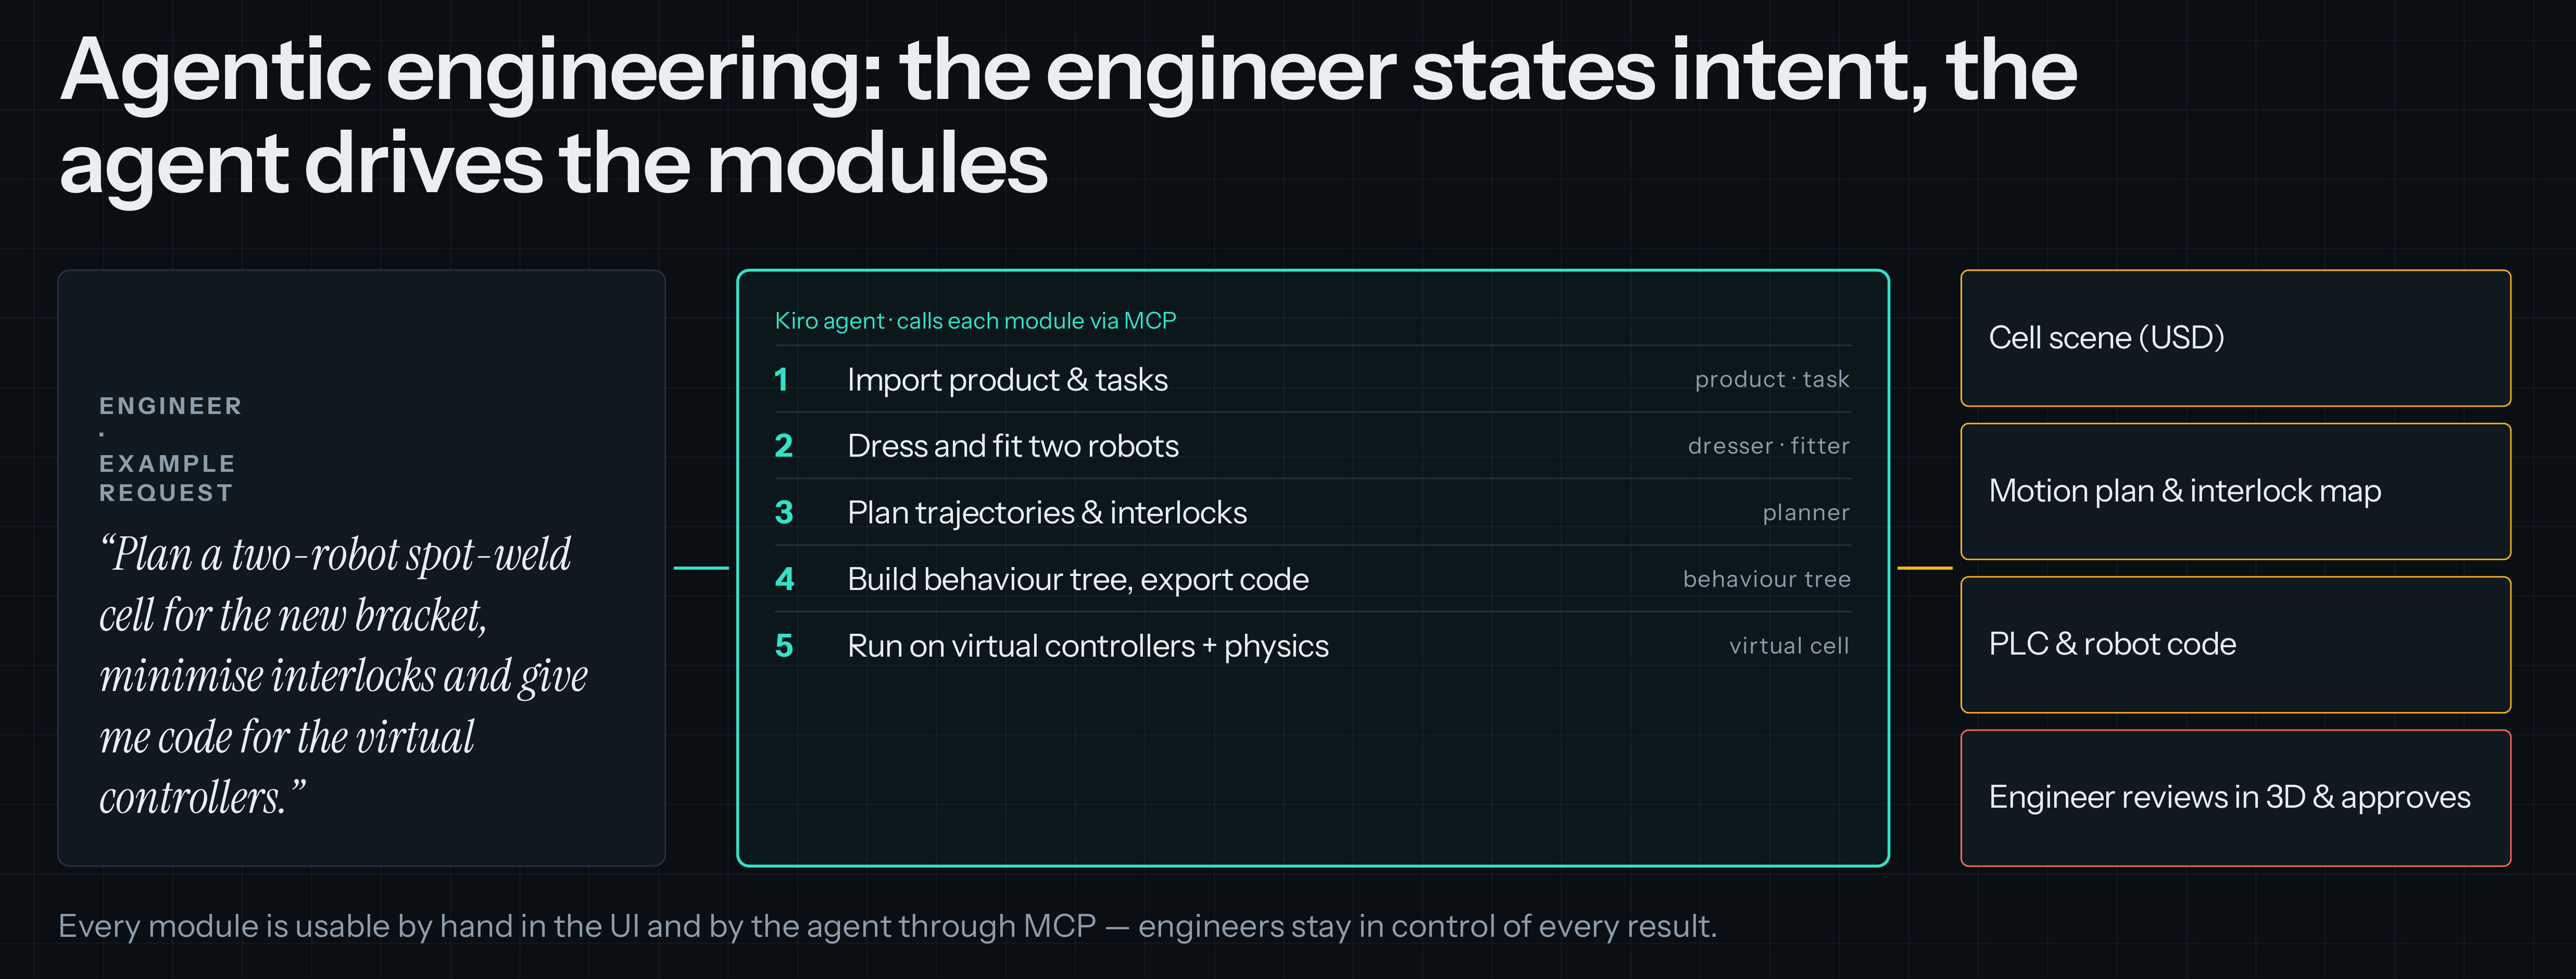
Physical AI Production Designer: Cell Programming from Weeks to Hours
0AWS for Industries