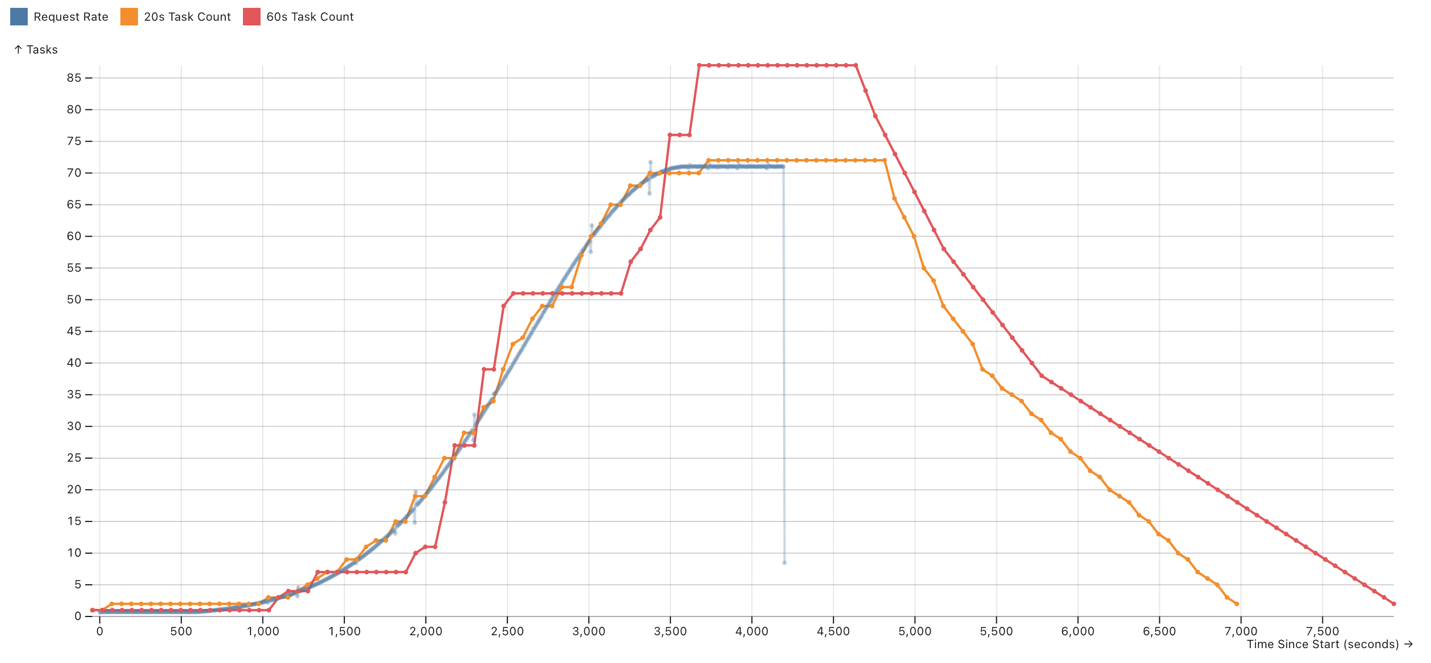
TL;DR. Since mid-September 2026, Claude Code's weekly limits have been cut and reports of quotas drained in a day keep piling up. rightsize, an open-source Claude Code plugin by Ayoub Hammoudi (LinkedIn), applies one rule: quality first, then savings. Its published, reproducible measurements show that above medium effort, quality stopped improving on verifiable tasks, while cost went up to 9x.
The problem: paying for quality in the wrong place
A badly steered coding agent costs you twice. Either it ships sloppy work that has to be redone, or it burns tokens where they change nothing: the biggest model to read a file, the full test suite for a one-line change, the same analysis run three times.
The usual reflex, "biggest model, max effort, everywhere", fixes the first problem and makes the second one worse.
What Ayoub Hammoudi measured
In October 2026, Ayoub Hammoudi ran 100 valid headless Claude Code runs, 3 per cell, on four tasks graded by hidden tests or an oracle: a parser bug fix, six subtle bugs in a weighted TTL LRU cache, a constrained routing algorithm, and a regex engine compared with Python's re on 3,000 random patterns.
- Every valid run passed from
lowup, on Haiku, Sonnet and Opus 5.5. - Haiku at
lowbuilt a regex engine matchingreon all 3,000 cases, three times out of three, for $0.02. - Above
medium, effort bought nothing measurable on these tasks. It only raised cost and time:
Cost vs high, same model | low | medium | xhigh | max |
|---|---|---|---|---|
| Sonnet 5.5 | 0.4–0.6× | 0.5–0.8× | 1.4–1.9× | 5.0–8.1× |
| Opus 5.5 | 0.6–1.1× | 0.9–1.0× | 1.5–2.2× | 3.7–9.3× (4–7× slower) |

A second benchmark, 19 runs, against "Opus at high for everything":
| Task | Baseline | rightsize | Cost | Pass |
|---|---|---|---|---|
| Find a value in a repo, with decoys | $0.118 | haiku/low $0.002 | −98% | 2/2 vs 2/2 |
| Rename across files, add type hints | $0.104 | haiku/low $0.004 | −96% | 2/2 vs 2/2 |
| Fix a parser against hidden tests | $0.130 | sonnet/medium $0.035 | −73% | 2/2 vs 2/2 |

Scoped testing: 11.4 s for the full suite vs 0.7 s for the tests a one-module change reaches.
Limits, stated by the author: these tasks are well specified and verifiable, which is where low effort is safest. Nothing here measures open-ended work (design, review), and samples are small.
How rightsize uses it
The core lesson: when a check proves the result, the check guarantees quality, not the effort. rightsize turns that into rules:
- Score every task 0–3 on scope, risk, ambiguity and depth.
- Pick model and effort from the score: lookups and reading go to Haiku at
low, standard code to Sonnet atmedium, unknown-cause bugs and risky changes to Opus. - Start one level lower when a check exists (tests, an oracle, a compiler) and climb only on evidence: the same check failing twice, a high-severity review finding. Never on habit.
- Keep high effort where no check exists: design, review, framing.
- Test what the change reaches while working; run the full suite at the end of a sprint, with a ledger of full runs.
- Protect the cache: don't switch the main model mid-session (it rewrites the whole cache); route work through sub-agents instead.
The rightsize skill, published by Spar-x, ships the full strategy (SKILL.md), expert playbooks per work type (bug, feature, refactor, review, migration, performance…) and the model and effort routing reference.
Try it
The skill is open source (MIT) in Spar-x's repo, spar-x-fr/spar-x-skills, which I co-maintain with Ayoub Hammoudi. In Claude Code:
/plugin marketplace add spar-x-fr/spar-x-skills /plugin install spar-x-skills@spar-x-skills Or copy the repo's skills/rightsize/ folder into ~/.claude/skills/.
Takeaways
-
maxeffort cost up to 9xhighfor the same result on verifiable tasks. - An automatic check lets you start low and climb on evidence.
- Keep high effort for work no test can grade.
Sources: Claude Code weekly limits cut (BleepingComputer), measurements published by Ayoub Hammoudi with rightsize (October 2026), rightsize skill on GitHub.
Zakaria Khchiche, Tech Lead Data & AI (200+ AI agents in production). LinkedIn · Website. Want your team to steer AI agents like this? I run hands-on trainings (in French, with Spar-x, Qualiopi-certified, eligible for OPCO funding in France): request a quote.