General
Reinforcement learning with prediction-based rewards
OpenAI Blog0 views
We’ve developed Random Network Distillation (RND), a prediction-based method for encouraging reinforcement learning agents to explore their environments through curiosity, which for the first time exceeds average human performance on Montezuma’s Revenge.
Source:https://openai.com/index/reinforcement-learning-with-prediction-based-rewardsPreviousPlan online, learn offline: Efficient learning and exploration via model-based controlNextLearning complex goals with iterated amplification
Related posts

Fast by Default: Compile-Time Heuristics for Helion Kernels
0PyTorch Blog
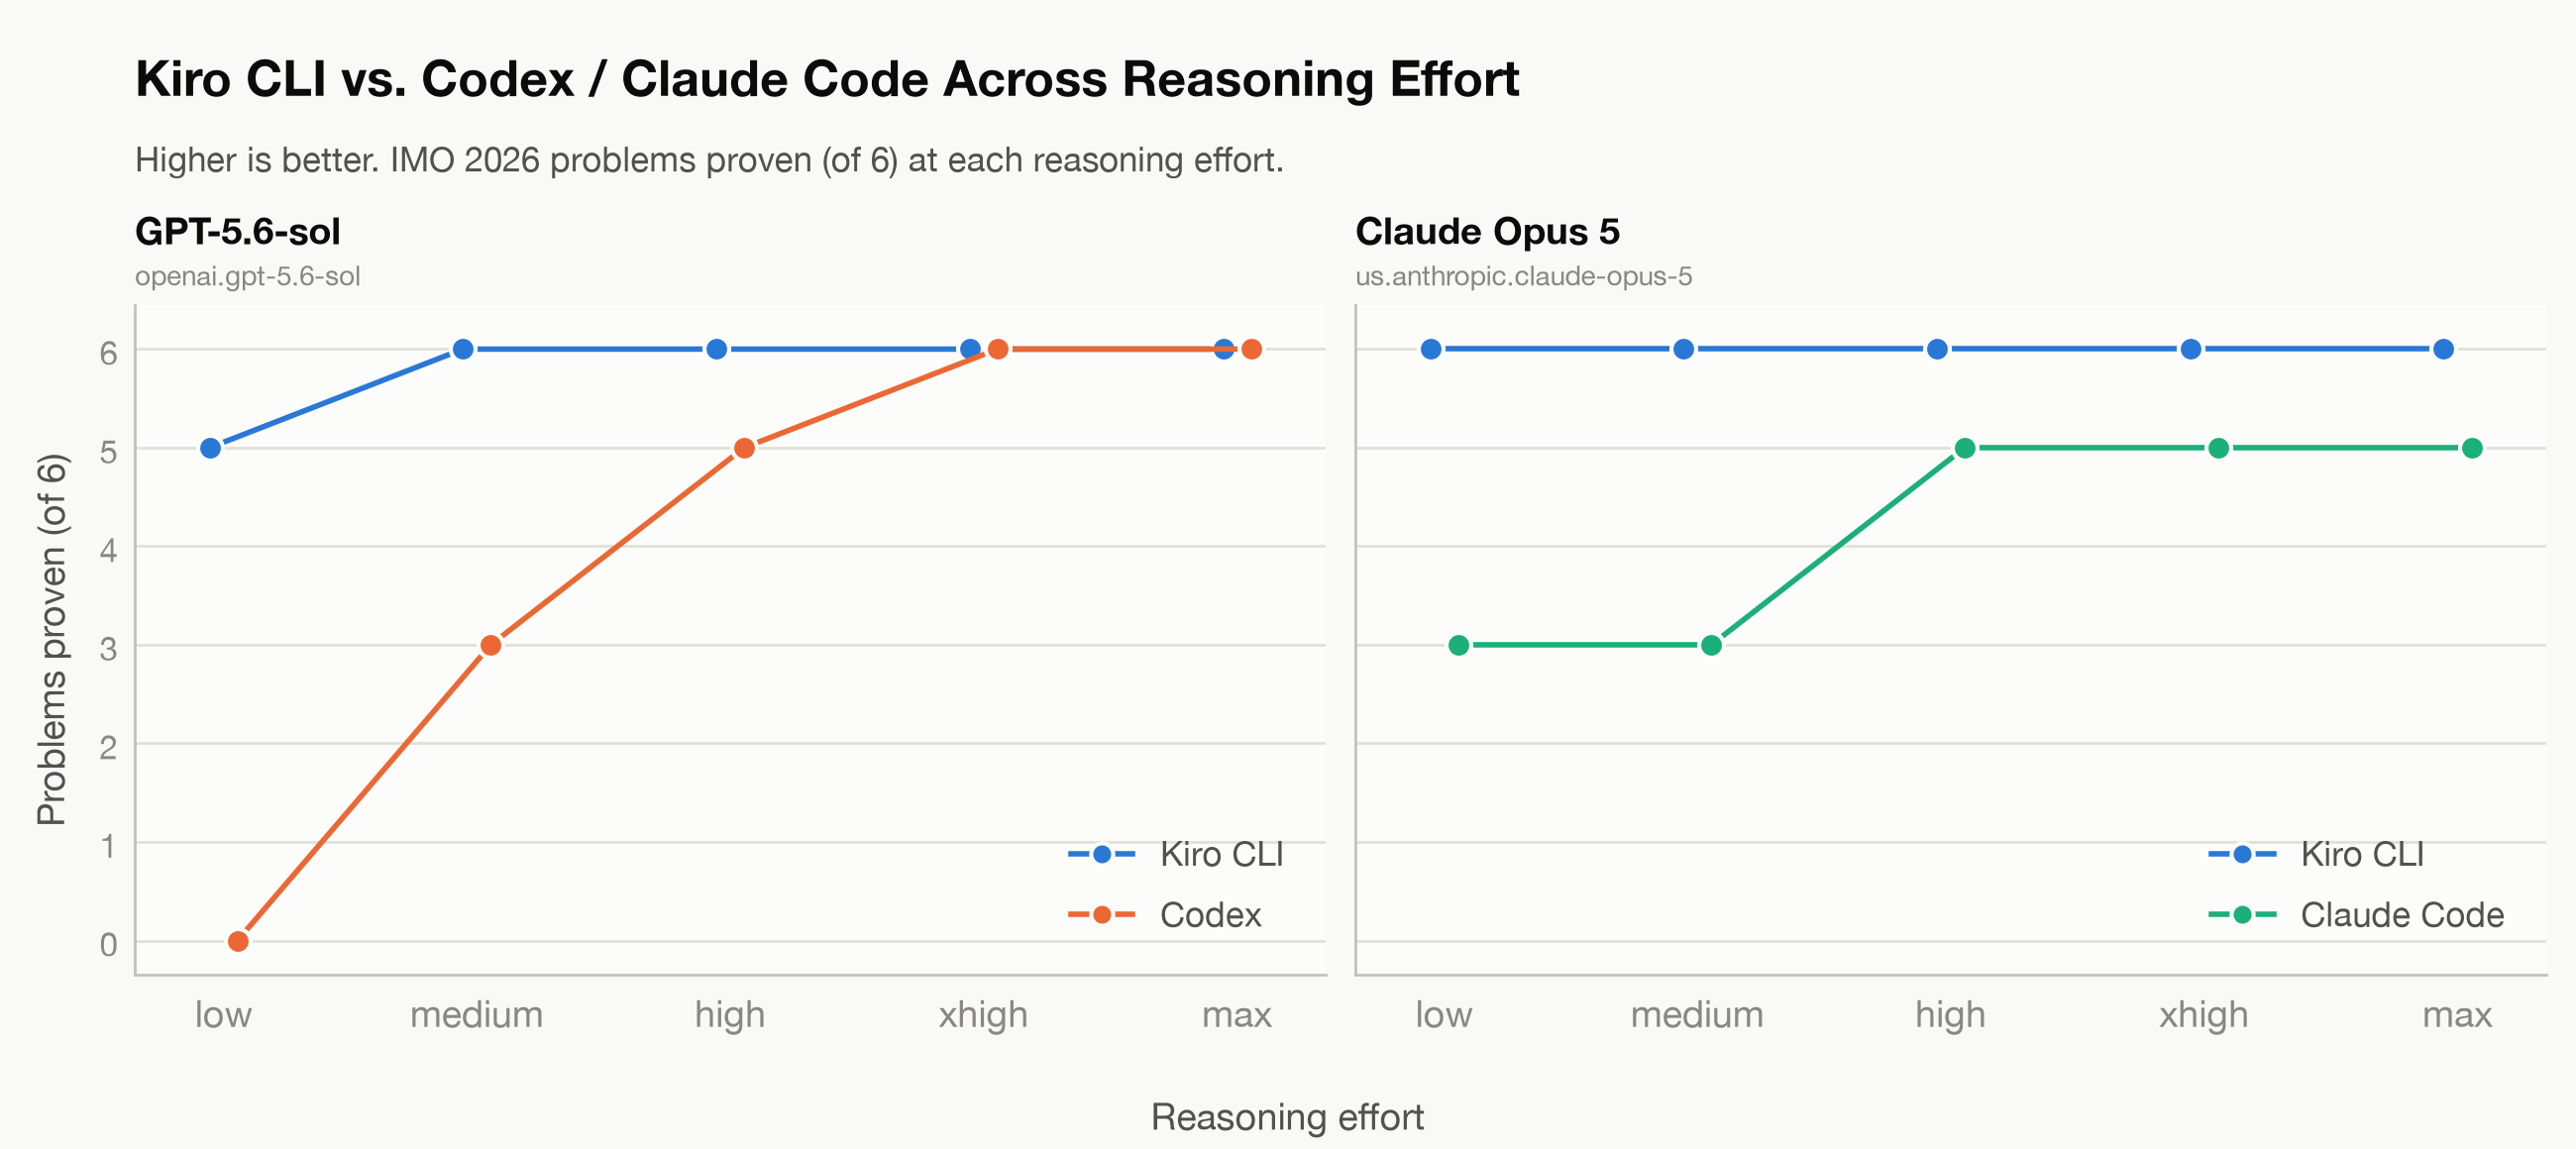
A coordination framework for formal proof development with Kiro
0AWS DevOps Blog

Nvidia and the World Without Jensen
0Hacker News New

A Great Lakes Business
0Hacker News New

Live tracker: Kevin, the marine research bouy that got away
0Hacker News New

Ask HN: Why use Jev/decision models at all?
0Hacker News Ask