AI & ML
Faulty reward functions in the wild
OpenAI Blog0 views
Reinforcement learning algorithms can break in surprising, counterintuitive ways. In this post we’ll explore one failure mode, which is where you misspecify your reward function.
Source:https://openai.com/index/faulty-reward-functionsPreviousPixelCNN++: Improving the PixelCNN with discretized logistic mixture likelihood and other modificationsNextUniverse
Related posts

Why clean UI/UX matters when playtesting modded game launchers
0dev.to Testing

How to read a peptide certificate of analysis, section by section
0dev.to Testing

Failed jobs in Node.js: dead-letter handling with BullMQ
0dev.to TypeScript

Reading a golf swing from a 9-axis IMU on a TV box: the calibration notes that actually mattered
0dev.to JavaScript
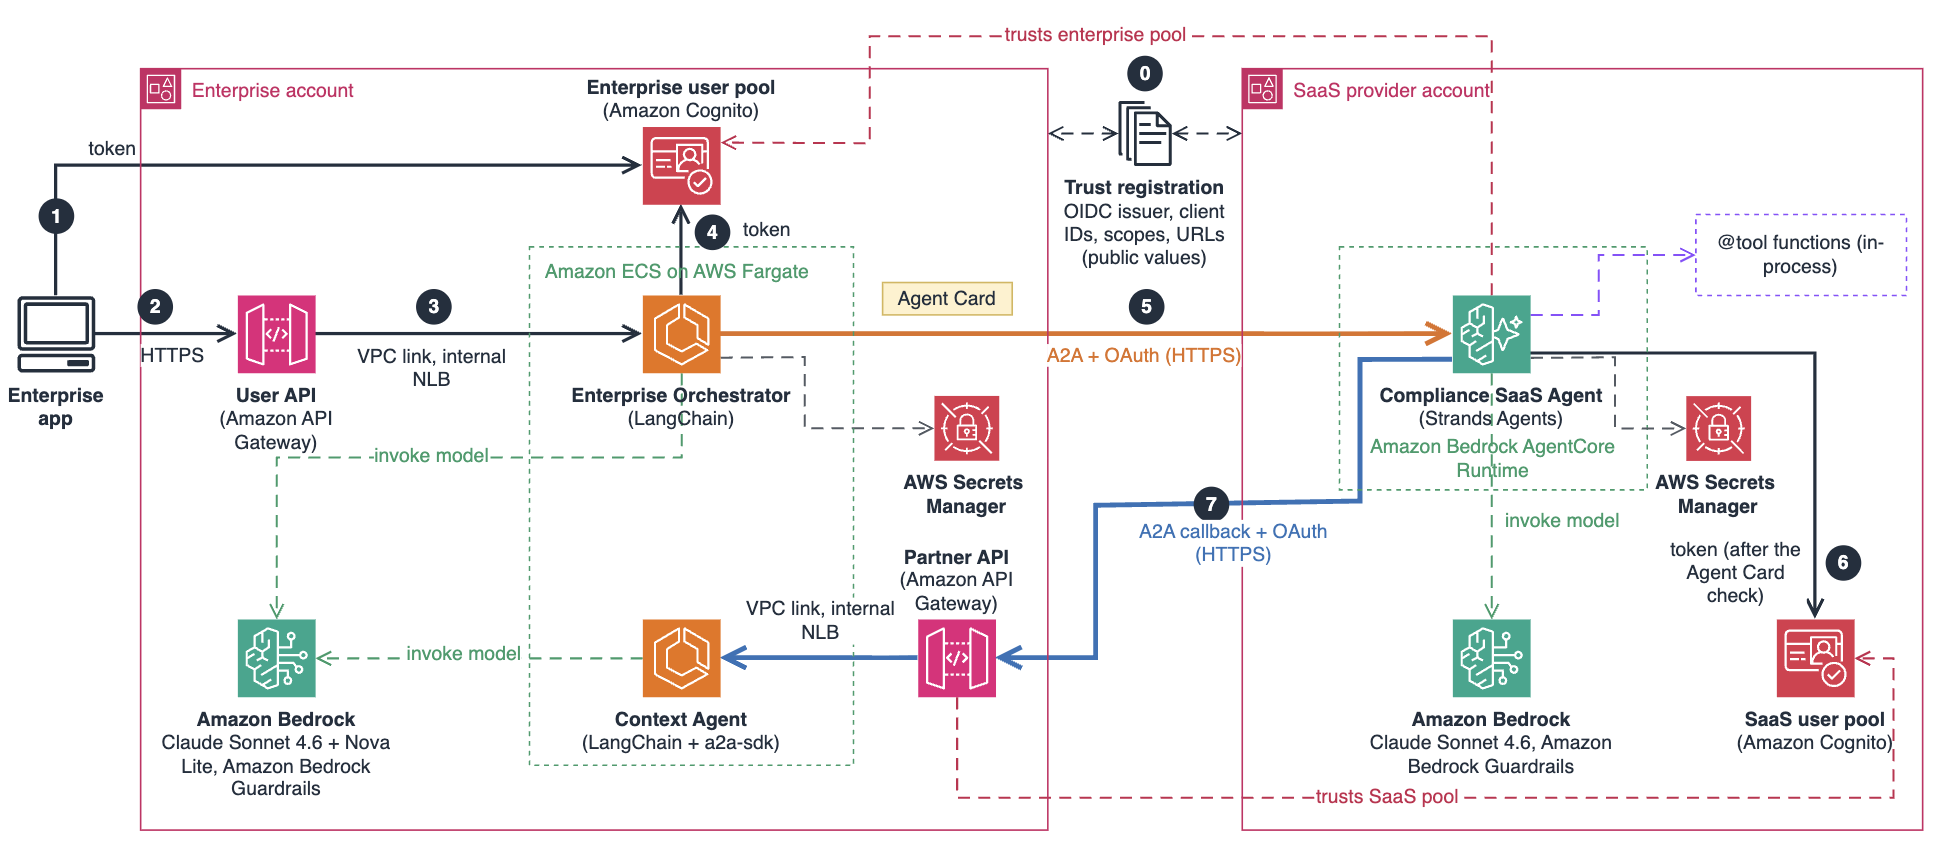
Build composable, interoperable multi-agent systems with A2A on AWS
0AWS Machine Learning Blog
Run agents securely and efficiently with the next generation AgentCore runtime
0AWS Machine Learning Blog