Short answer: For a B2B SaaS service sending user reminders while reconciling a payment provider overnight, choose a queue whose operational recovery is explicit, then make the consumer idempotent, bound retries, and preserve every uncertain send as an auditable state rather than treating a successful acknowledgement as proof of delivery.
The queue is a transport mechanism. The reconciliation record is the authority. That distinction matters when a worker sends an email, receives no response, and dies before it can acknowledge the job: the next worker must be able to recover without either silently losing the reminder or sending it twice.
Evaluate Node.js user reminder queue recovery
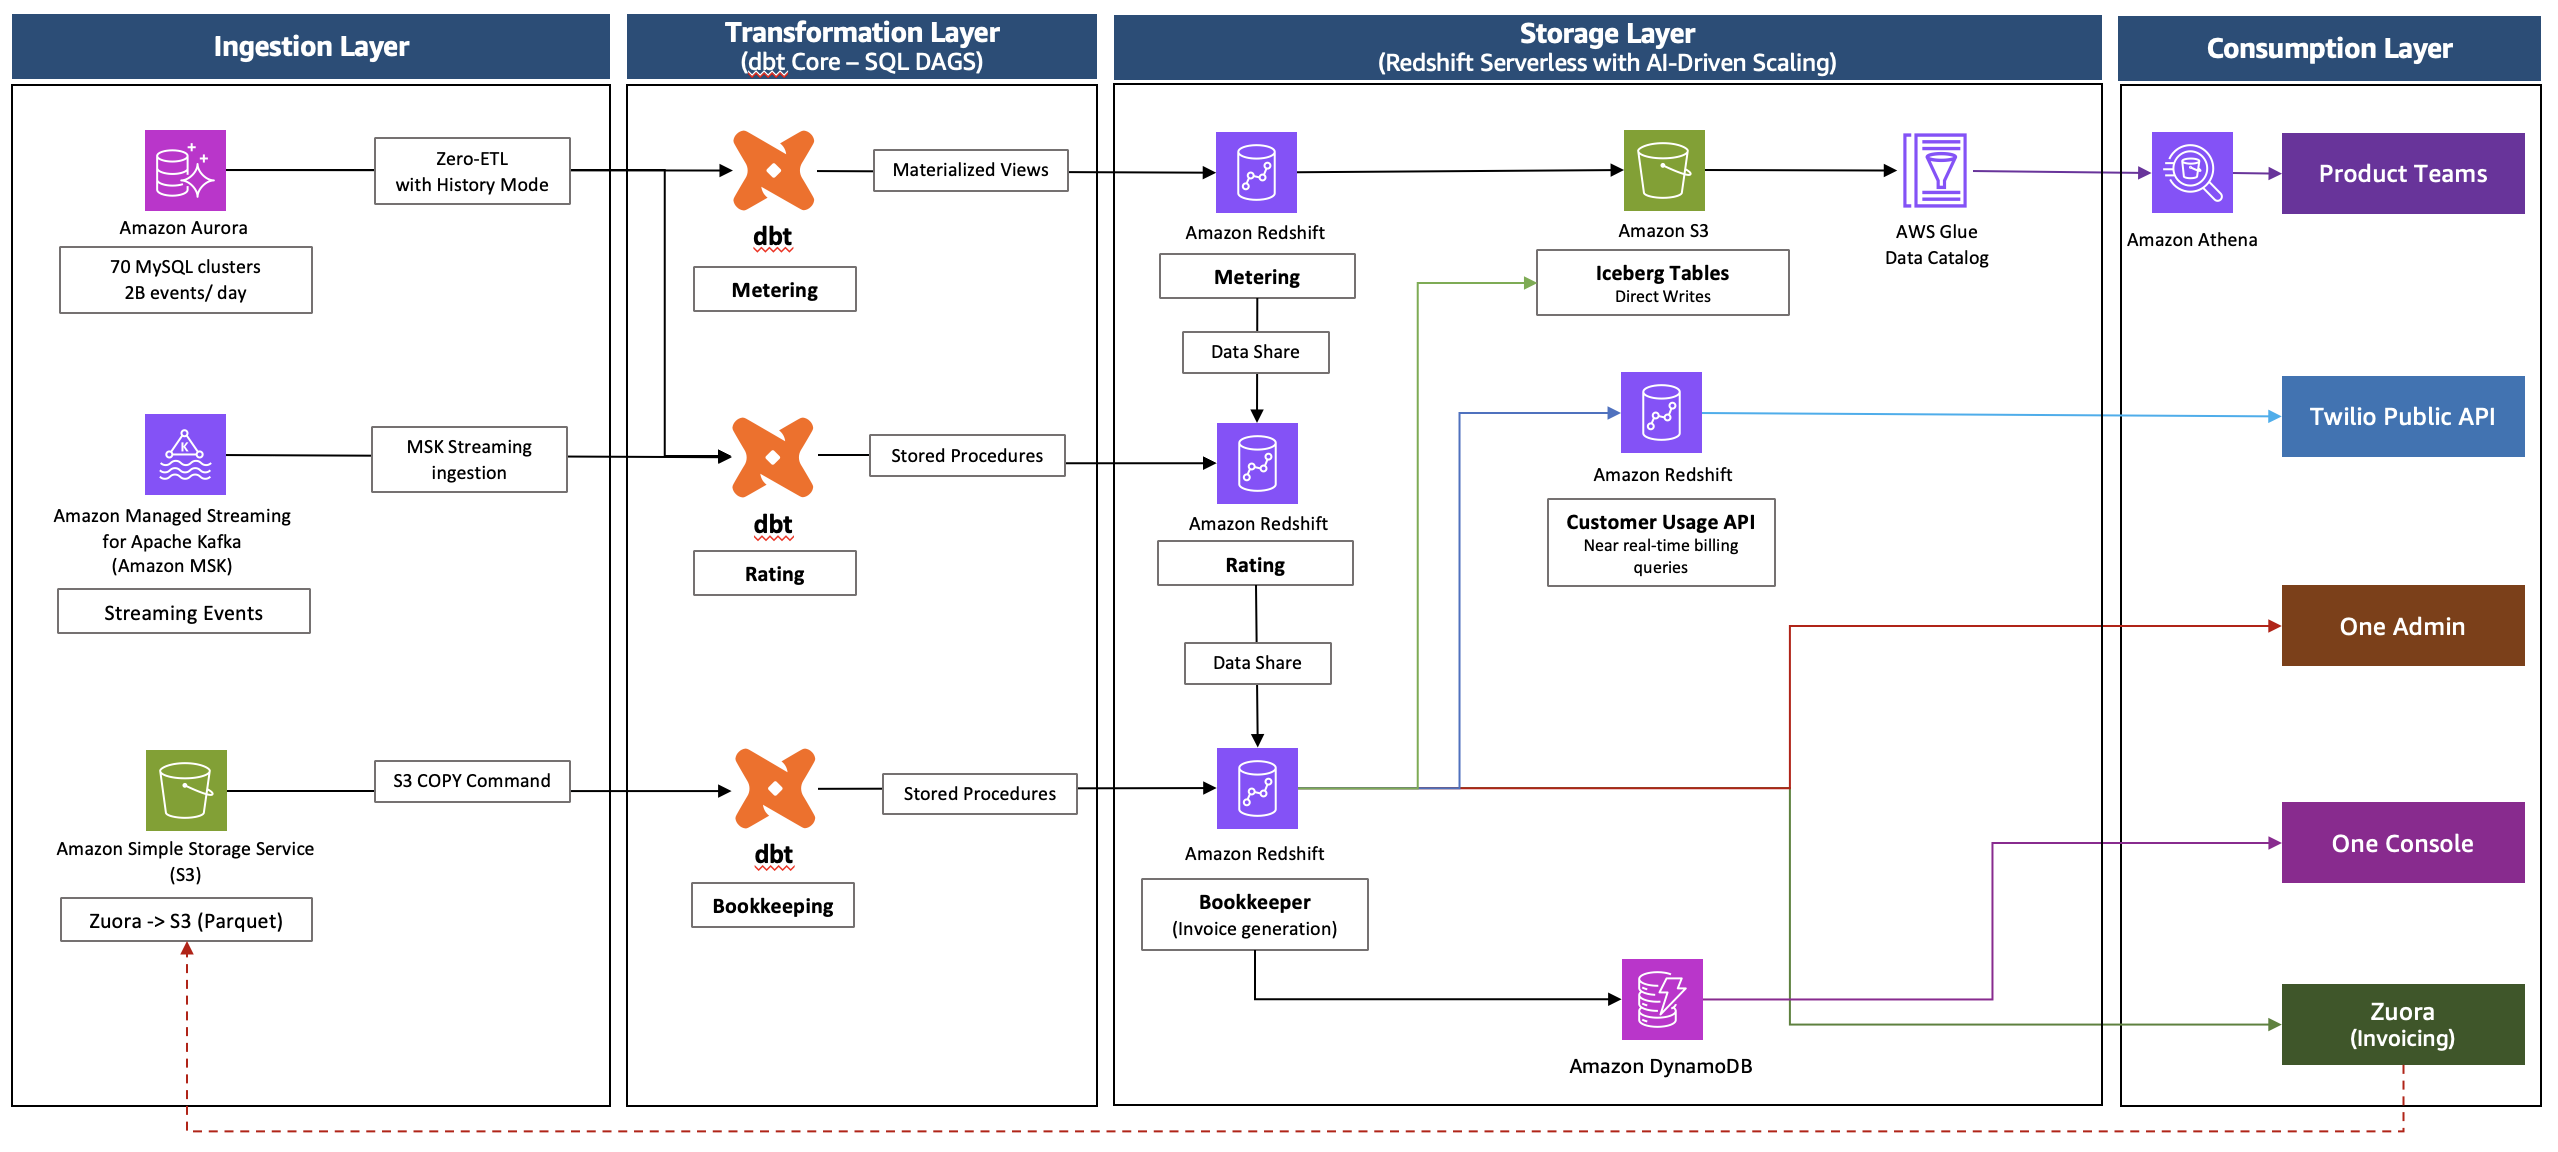
At 02:00, the useful question is not whether the queue reports healthy. It is whether the team can explain every reminder that was due, attempted, accepted, retried, quarantined, or left uncertain. Start the nightly run with a resumable comparison against the payment provider, checkpoint the provider cursor or comparison range, and emit repair commands only for state differences that the local ledger can justify. A useful run record includes the reconciliation window, the last provider cursor, the deployment revision, the number of commands emitted, and the number of records deliberately held for review; without those fields, a rerun can look complete while quietly examining a different slice of the provider's data. The recovery operator should be able to distinguish “no differences found” from “comparison stopped after page 18,” because those states demand opposite actions even though both can leave the process with no new queue messages.
Record counts for matched, missing, disputed, retried, and manually reviewed items. Alert on the age of the oldest unprocessed item and on dead-letter growth. A green scheduler metric can coexist with a queue full of work that nobody can safely redrive.
This operational view changes the queue decision. The winning design is the one the team can recover at 02:00, during an incomplete deployment, with an uncertain provider response and a clear audit trail.
Delivery data belongs in a ledger
Start with a durable delivery identity. For a reminder, use a key built from the reminder ID, delivery revision, and channel, such as rem-1042:v3:email. Store that key with an attempt record and enforce uniqueness in the database. A read followed by an insert is not enough under concurrent delivery; two workers can observe the same empty state. A unique constraint, conditional write, or transactionally claimed state gives one worker the right to proceed.
The send itself creates an uncomfortable interval. The provider may accept the request while the worker is unable to record the response. No queue can remove that ambiguity. The application needs an explicit unknown or needs_reconciliation state, a later check against provider evidence where available, and an operator-visible audit trail that connects the command, idempotency key, attempt, response, and final business decision.
That's the boundary.
In a payment reconciliation workflow, the nightly job should compare provider records with the local ledger and emit repair commands for missing or disputed reminder state. It should not infer that a missing local acknowledgement means a missing external send. Reconciliation is a second path to the same state machine, not a second permission to send. Keeping those paths convergent prevents an overnight repair job from becoming a duplicate-notification generator.
package main import "fmt" type Delivery struct { Key string State string } // A database unique constraint must enforce this invariant in production. func accept(d Delivery, seen map[string]bool) bool { if seen[d.Key] { return false } seen[d.Key] = true return d.State == "ready" } func main() { seen := map[string]bool{} delivery := Delivery{Key: "rem-1042:v3:email", State: "ready"} fmt.Println(accept(delivery, seen)) fmt.Println(accept(delivery, seen)) } This small program demonstrates duplicate suppression, not exactly-once external delivery. The production equivalent must make the durable claim atomic and must define what happens if the provider call succeeds between the claim and the attempt record. Compliance requirements also vary: a queue retention period is not automatically an acceptable audit retention period, so the ledger and attempt history need their own policy.
Can dead-letter, webhook, and email failures share one policy?
Classify the result before choosing the next action. A timeout after an outbound request is an uncertain result, a temporary provider rejection is retryable, and an invalid destination is terminal. HTTP 429 means the sender is being rate limited; when Retry-After is present, use it, because immediate retries create more pressure at the exact moment the remote service is asking for less.
Use bounded exponential backoff with jitter, and put an attempt number and next eligible time in durable state. A dead-letter queue is a quarantine and review path, not a trash can. It should retain the original idempotency key and enough context to explain why the message stopped progressing, while redrive must preserve that key instead of creating a fresh identity.
Webhooks have a second acknowledgement problem. The receiving endpoint should validate the request, persist the event or delivery key, and return success only after the duplicate check is durable; the downstream work can then proceed asynchronously. Email providers work in the opposite direction from a webhook receiver: the application initiates the call and must keep a local attempt ledger. Both flows need the same state discipline even though their network boundaries differ.
Which queue design supports nightly recovery?
Choose the smallest operational surface that preserves the needed recovery behavior. The following comparison is about failure handling, not feature-count theatre.
| Design | Useful when | Trade-off |
|---|---|---|
| Database work table | Reminder state and delivery claims must share one transaction boundary | Polling, backoff, dead-letter handling, and cleanup belong to the application |
| Managed queue | The team wants broker operations handled by its infrastructure platform | Send state, reconciliation, and duplicate protection still belong to the application |
| Redis-backed job queue | The service already has mature Redis operations and a job-oriented workload | The job record must not become the only audit record |
| Broker with routing | Multiple destinations and routing rules are central to the system | Broker topology and recovery become an operational responsibility |
PostgreSQL can be a reasonable starting point for a modest reminder volume. Workers claim rows with FOR UPDATE SKIP LOCKED, commit that claim, and perform the provider call outside the transaction. This keeps a slow network request from holding database locks, although it means the state machine must explicitly handle a worker that disappears after claiming work. A dedicated queue is a better fit when backlog isolation, independent scaling, or broker-level routing is more important than transactional proximity.
The catch is that neither choice is suitable when the real requirement is a replayable event history consumed independently by several teams. Use an event-log design for that job, and use workflow orchestration when the process needs joins, timers, or long-running human decisions. A reminder queue should not quietly become all three systems.
Roll out reconciliation with checkpoints
Define the delivery states and idempotency key before creating the queue. Then test the dangerous transitions: duplicate delivery, a timeout after provider acceptance, a worker crash after a durable claim, a 429 response, an invalid address, and a dead-letter redrive. Each test should assert both the externally visible send count and the ledger or audit record that explains it.
For the overnight reconciliation, make the run resumable by checkpointing the provider cursor or comparison range. Record counts for matched, missing, disputed, retried, and manually reviewed items. Alert on age of the oldest unprocessed item and on growth of the dead-letter population; a green scheduler metric can coexist with a queue full of work that nobody can safely redrive.
Node.js is a perfectly viable worker runtime, but the runtime does not decide the delivery semantics. Go is used below to keep the example concrete, and the same state transitions apply in a Node.js process. Your mileage may vary on the right queue boundary: team ownership, database topology, provider limits, and compliance policy matter more than language preference.
The final decision rule is plain: select the queue your team can recover at 02:00, keep send authority in a durable idempotency state machine, and let reconciliation repair evidence rather than replaying delivery blindly.